Large-repository navigation
Finding the files and line ranges connected to a bug, feature, or execution path without manually exploring every directory.
Independent tool overview
SWE-grep is Cognition's specialist code-retrieval model for finding relevant files and line ranges with parallel searches. It powers Fast Context inside the company's coding products; it is not a standalone IDE, general coding model, or separately priced public API.
Visit the official SWE-grep site ↗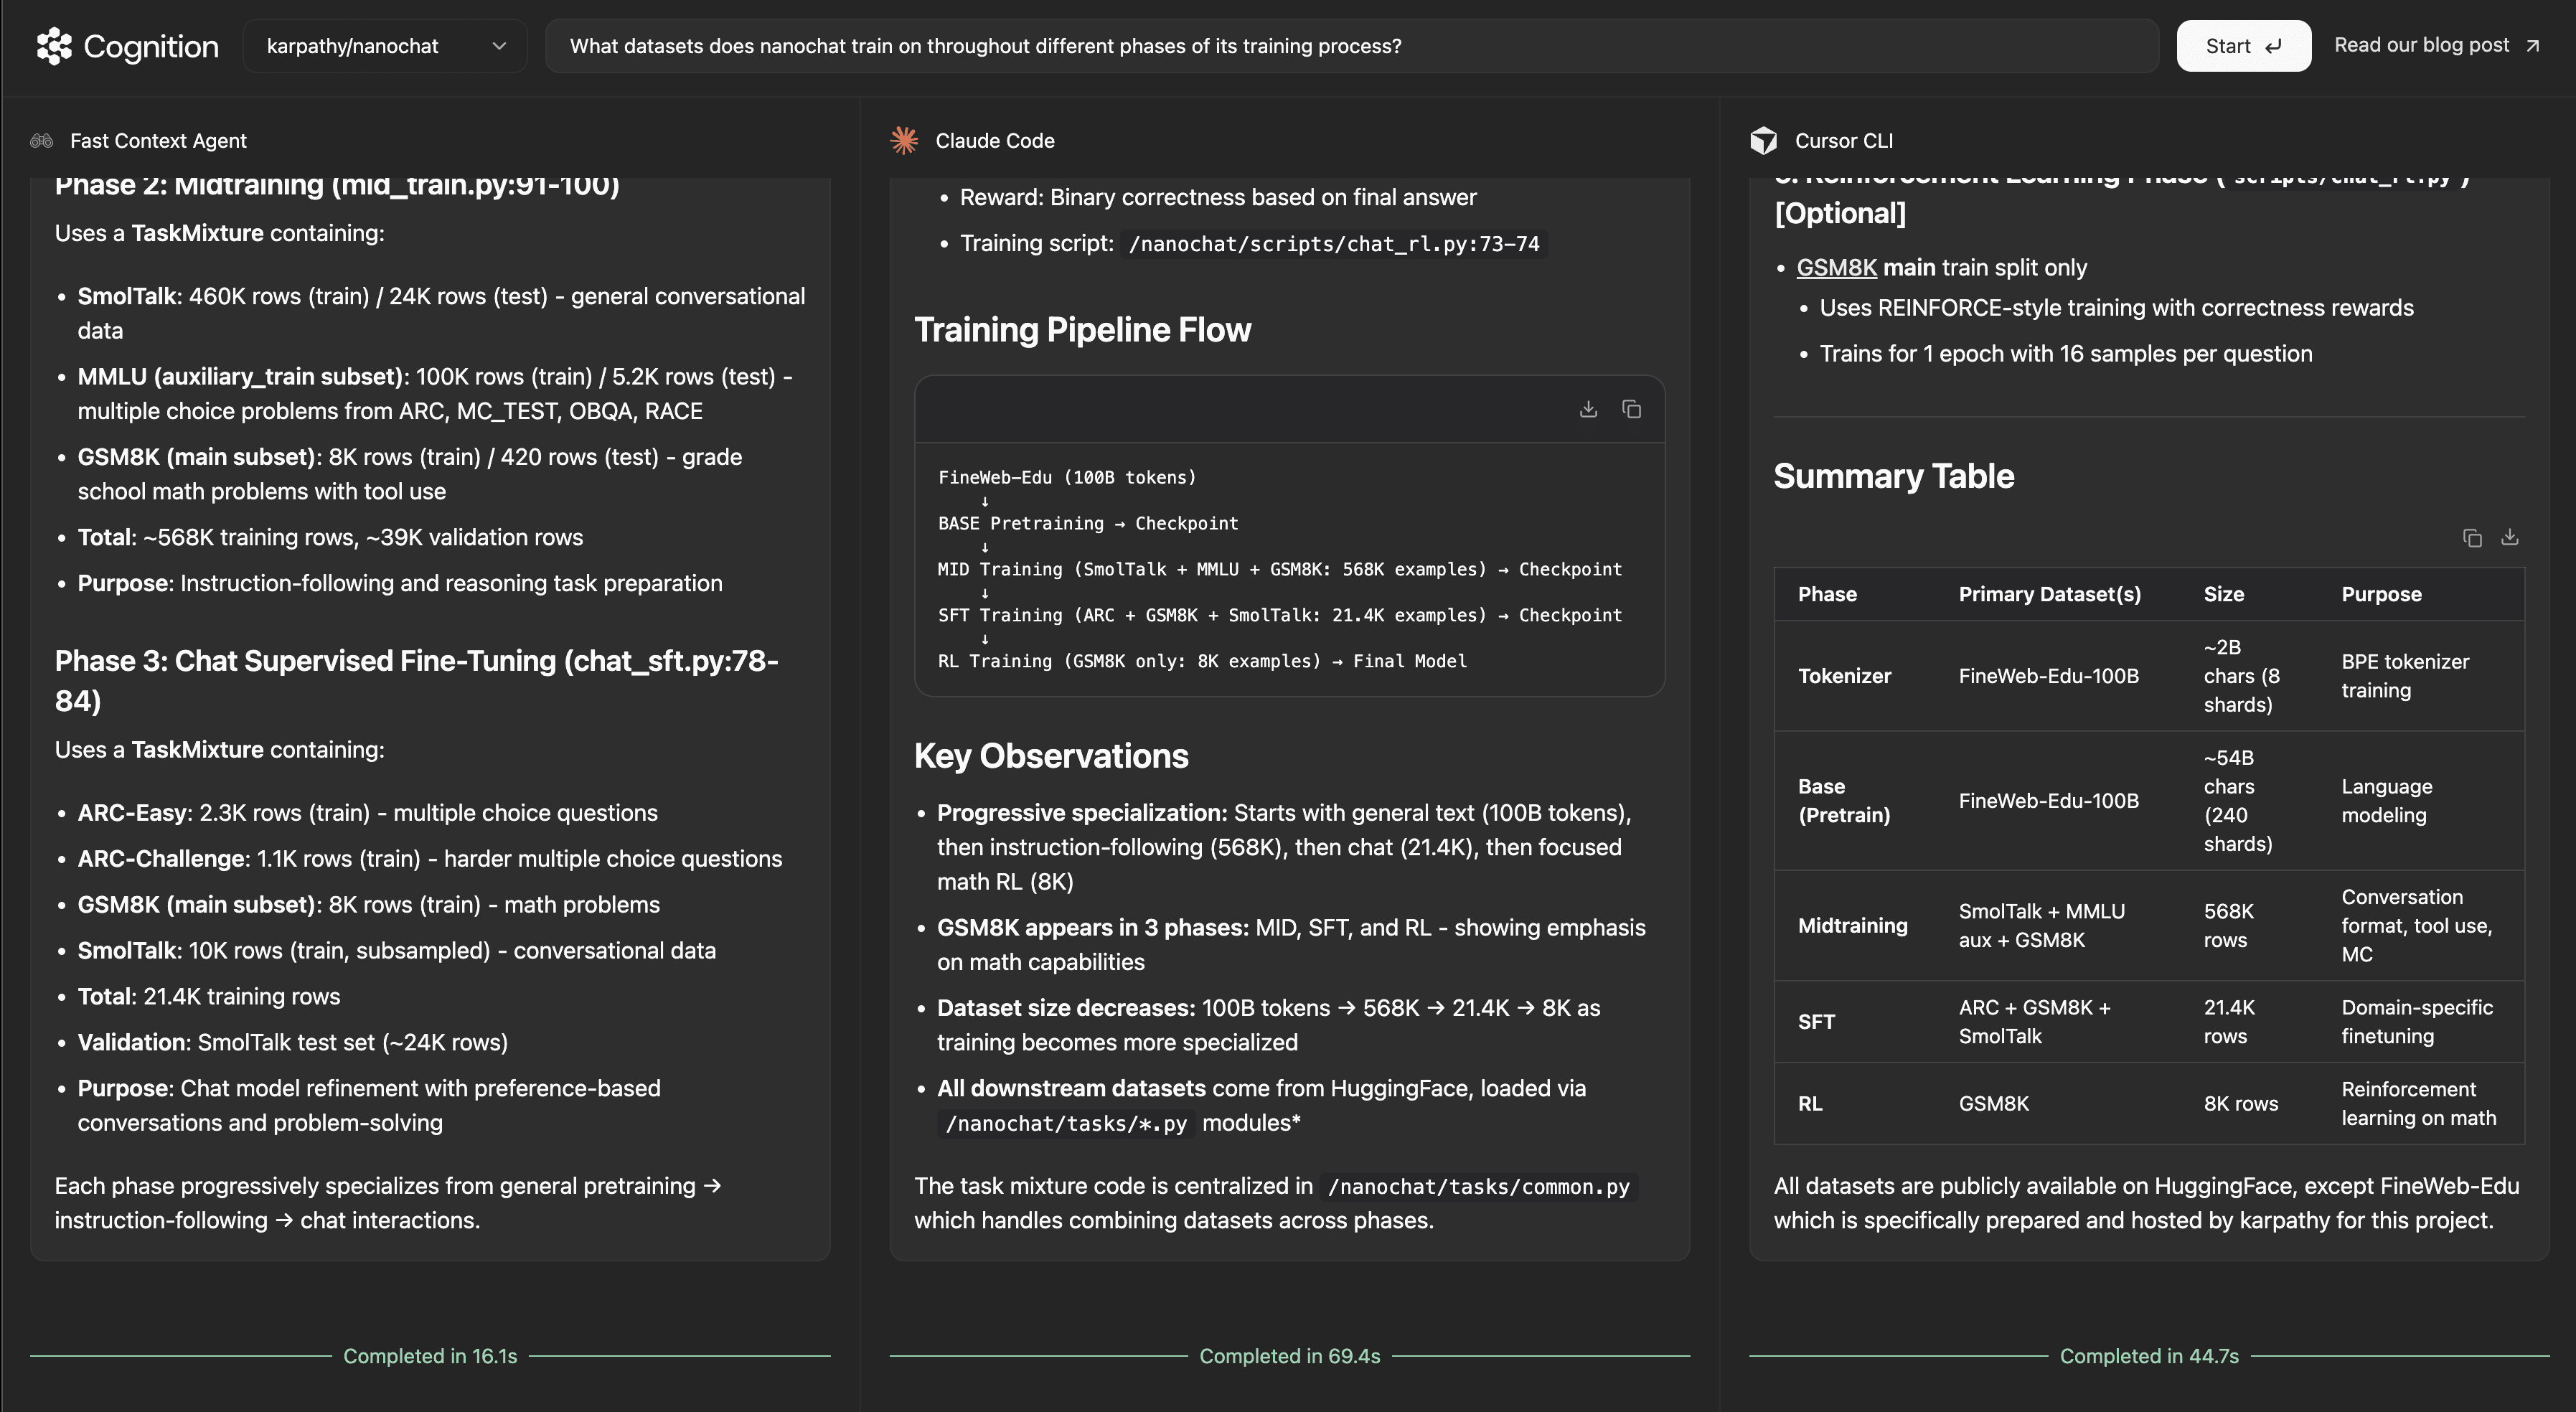
Overview
SWE-grep and the smaller SWE-grep-mini were trained for one narrow part of agentic software work: locating the right code quickly. Rather than asking a large coding model to spend many sequential turns exploring a repository, the models can issue up to eight parallel search or read calls per turn and finish within four turns.
Cognition introduced the models as the engine behind Fast Context in Windsurf, which became the foundation for Devin Desktop. The retrieval subagent returns relevant files and line ranges to the main coding agent, conserving the main model's context for reasoning and implementation.
This specialization is the main reason to consider SWE-grep, but it also defines the boundary: users access the capability through Cognition's product experience rather than choosing SWE-grep as an independent model endpoint.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Finding the files and line ranges connected to a bug, feature, or execution path without manually exploring every directory.
Teams that want a fast retrieval subagent to prepare context before a more capable model reasons about a change.
Workflows that benefit from separating repository search from code generation and implementation.
Capabilities
SWE-grep was trained to issue as many as eight grep, glob, and file-read calls in parallel at each exploration turn.
Its launch configuration used three exploration turns and one answer turn, reducing repeated network and inference round trips.
Fast Context is designed to return specific files and line ranges rather than a free-form summary that could obscure the underlying evidence.
Cognition introduced SWE-grep alongside distilled SWE-grep-mini, with the mini variant optimized for even faster retrieval.
The models use a focused, cross-platform tool set such as grep, read, and glob instead of a broad code-execution environment.
Process
Step 1
Give the coding agent a concrete task, bug, or code-path question that requires finding relevant context.
Step 2
The retrieval subagent searches multiple parts of the repository in parallel and identifies the strongest file and line-range matches.
Step 3
A general coding model receives the selected context and uses it to explain, plan, or implement the requested change.
Step 4
Review the cited files and run normal tests because fast retrieval can still omit a rare dependency or choose an incomplete path.
Cost
Cognition does not list SWE-grep as a separately priced model or public API. Fast Context appears in the current Devin platform comparison; access is packaged with Devin Desktop plans rather than purchased as a standalone SWE-grep subscription.
Not separately sold
There is no distinct SWE-grep plan on Cognition's current pricing page.
$0
The entry plan provides a light agent quota, limited model availability, unlimited inline edits, and unlimited Tab completions.
$20/month
The individual paid plan adds higher quotas, full model availability, frontier models, and cloud agents.
$200/month
The power-user plan includes everything in Pro with significantly higher quotas.
$80/month + $40/full seat
The team plan adds shared administration, collaboration, centralized billing, and support.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Coding
Devin Desktop is the current Cognition product surface for Fast Context and the clearest route for using the capability.
Explore Devin Desktop →Coding
Claude Code performs agentic repository search and implementation in one workflow, with broader coding abilities but a less narrowly specialized retrieval model.
Explore Claude Code →Coding
Cursor combines codebase search, chat, and agentic editing in an IDE for teams comparing complete coding environments.
Explore Cursor →Questions
SWE-grep is a Cognition model specialized in fast, multi-turn codebase retrieval. It searches for relevant files and line ranges so a main coding agent can work with a smaller, more useful context.
Cognition does not list a standalone SWE-grep API or individual model price. The company presents it as the technology behind Fast Context in its coding product experience.
No. SWE-grep is a retrieval model. Devin Desktop is the broader agentic development environment that grew from Windsurf and includes coding, agent management, editing, and cloud-agent workflows.
At launch, Cognition reported more than 650 output tokens per second for SWE-grep and more than 2,800 for SWE-grep-mini on Cerebras, plus order-of-magnitude latency gains on its internal retrieval evaluation. Those are vendor results, not guarantees for every repository.
Bottom line
SWE-grep is a smart architectural idea for reducing the repository-search tax inside coding agents. It is most relevant to developers evaluating Fast Context through Devin Desktop, not buyers looking for an independent model endpoint. Judge it on retrieval accuracy and end-to-end task time in your own codebase rather than headline token speed alone.
Visit SWE-grep website ↗
Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.

Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.

To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.

Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.

Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.