Agentic enterprise systems
Build reasoning, planning, coding, tool-calling, and retrieval agents under an organization-controlled deployment.
Independent tool overview
NVIDIA Nemotron 3 is a family of downloadable models and hosted NIM endpoints for agentic reasoning, coding, tool use, long-context work, multimodal understanding, and retrieval.
Visit the official Nemotron 3 site ↗
Overview
Nemotron 3 is NVIDIA's open-model family for developers building specialized AI agents and enterprise inference systems. Its core Nano, Super, and Ultra language models use hybrid Mamba-Transformer mixture-of-experts architectures that activate only part of their total parameter count, aiming to balance reasoning quality, long context, and serving efficiency.
The family has expanded beyond the original three sizes. Nemotron 3 Nano Omni adds image, video, audio, and text understanding, while Nemotron 3 Embed supports multilingual semantic search and retrieval. Weights, model cards, training resources, and deployment instructions are available through NVIDIA and Hugging Face, with free prototype endpoints and production options through NIM, partner endpoints, or self-hosted infrastructure.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Build reasoning, planning, coding, tool-calling, and retrieval agents under an organization-controlled deployment.
Use mixture-of-experts models that activate a smaller parameter subset per token than their total model size.
Use Nano Omni for text output from images, video, audio, documents, OCR, and graphical interfaces.
Capabilities
Nano has 30B total and about 3.5B active parameters, Super has 120B total and 12B active, and Ultra has 550B total and 55B active.
The chat template can enable or disable thinking mode to trade additional reasoning work for speed and cost.
Super and Ultra support context windows up to one million tokens for large repositories, documents, and multi-step agent histories.
The core models are trained for instruction following, code, planning, retrieval, and tool-calling workflows.
A roughly 31B-total, 3B-active model that understands text, images, audio, and video and returns text with up to 256K context.
Provides downloadable checkpoints plus integrations for vLLM, SGLang, TensorRT-LLM, Ollama, llama.cpp, NVIDIA NIM, and partner services.
Process
Step 1
Choose Nano for efficiency, Super for stronger long-context agents, Ultra for demanding reasoning, Omni for multimodal input, or Embed for retrieval.
Step 2
Review the exact model card, governing license, supported precision, memory requirement, and deployment geography before committing.
Step 3
Test prompts, tool schemas, context behavior, and output quality through NVIDIA's free trial endpoint or another provider.
Step 4
Measure accuracy, latency, throughput, safety, and total cost against the organization's real documents and agent workflows.
Step 5
Select NIM, a partner endpoint, or self-hosted inference, then add application-level permissions, observability, evaluation, and fallback controls.
Cost
Nemotron 3 model weights can be downloaded under the license attached to each checkpoint, and NVIDIA offers free prototype endpoints. Production cost depends on GPU infrastructure, NVIDIA NIM licensing or entitlement, cloud and partner endpoint rates, model size, precision, context length, and traffic.
No model download fee
Run eligible Nemotron 3 checkpoints on infrastructure you operate.
Free trial endpoint
Prototype through an OpenAI-compatible hosted API subject to NVIDIA's trial terms and limits.
Infrastructure or provider pricing varies
Use NVIDIA NIM, partner endpoints, or self-managed GPUs for production inference.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Coding
Choose Meta Llama when ecosystem breadth and broad third-party deployment support are the main priorities.
Explore Meta Llama Models →Business Operations
Choose DeepSeek for another family of downloadable reasoning and coding models with separate hosted access.
Explore DeepSeek →Consumer
Choose Qwen3.5 Small when compact open models and more modest local hardware targets are more important than NVIDIA-stack optimization.
Explore Qwen3.5 Small →Questions
No. It is a family that includes Nano, Super, Ultra, Nano Omni, embedding models, multiple precisions, and base or post-trained variants.
Nano is 30B total with about 3.5B active parameters, Super is 120B total with 12B active, and Ultra is 550B total with 55B active.
The core Nano, Super, and Ultra chat models are text models. Nemotron 3 Nano Omni accepts video, audio, image, and text inputs and returns text.
Weights can be downloaded without a per-model purchase fee and NVIDIA offers free trial endpoints, but self-hosting, production endpoints, NIM, cloud GPUs, and operations can create substantial costs.
NVIDIA model cards mark major Nemotron 3 checkpoints as ready for commercial use, but the exact governing license differs by checkpoint and must be reviewed before deployment.
Bottom line
Nemotron 3 is particularly attractive to teams that want inspectable, deployable agent models and already operate NVIDIA infrastructure. Nano is the practical starting point, while Super and Ultra should be selected only after workload-specific testing justifies their much larger hardware footprint; teams should treat each checkpoint as a separate technical and licensing decision.
Visit Nemotron 3 website ↗
Lux - OpenAGI's fast, cost-effective computer-use model that tops industry benchmarks

Manus: AI agents that can do research, analysis and productivity tasks.
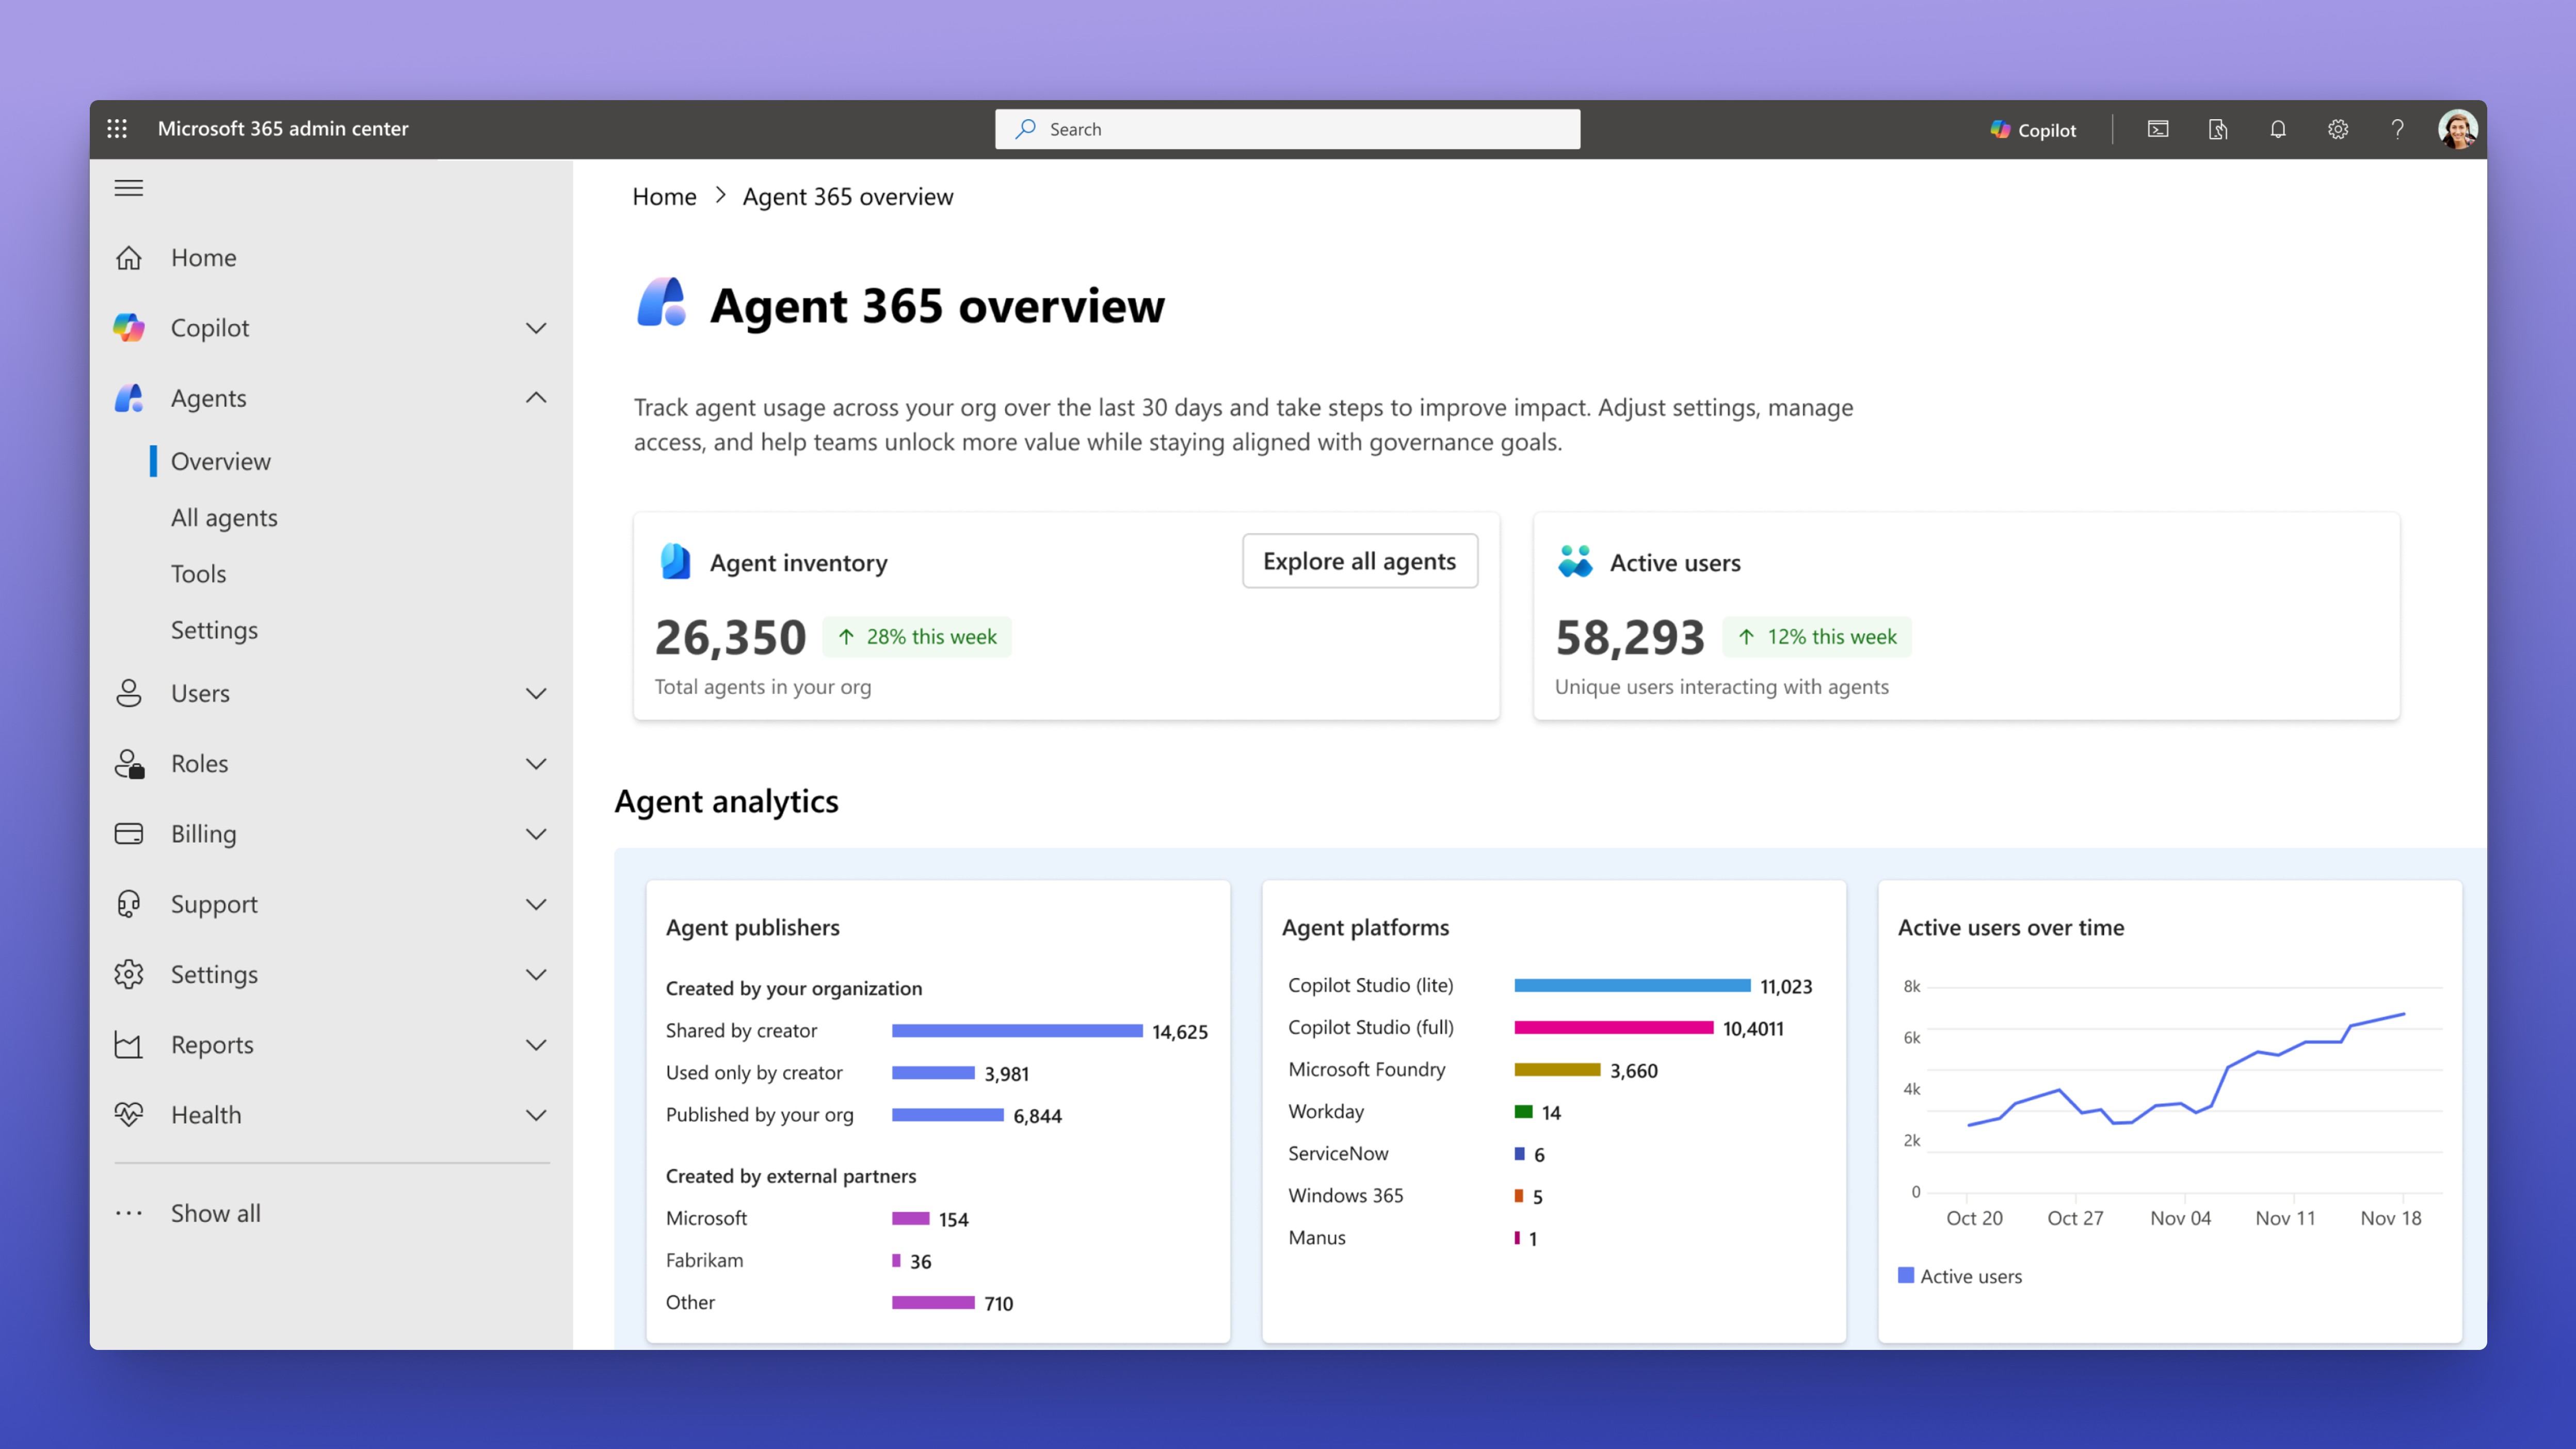
Agent 365 - Microsoft's platform for managing, securing, and governing AI agents, with capabilities like agent registry, performance analytics, and more.
Claude in Chrome - Agentic browser extension to use Anthropic's Claude directly in Google Chrome

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.