Document intelligence
Analyze long documents, charts, tables, screenshots, and scanned visual layouts in a shared context.
Independent tool overview
NVIDIA Nemotron 3 Nano Omni is a commercially usable open-weight model that understands video, audio, images, and text and returns text for agent and document workflows.
Visit the official Nemotron 3 Nano Omni site ↗
Overview
Nemotron 3 Nano Omni is NVIDIA's multimodal perception-and-reasoning model for developers building document, audio, video, and computer-use agents. It accepts video, audio, images, and text in one context, then produces text, JSON, tool calls, or timestamped transcription output.
The model uses a 31-billion-parameter hybrid Mamba2-Transformer mixture-of-experts architecture while activating roughly 3 billion parameters per token. NVIDIA publishes a maximum 256K-token context and BF16, FP8, and NVFP4 checkpoints under the NVIDIA Open Model Agreement.
Its strongest fit is as the eyes and ears of a larger agent system: extracting information from complex documents, interpreting a screen, connecting speech to video, or summarizing mixed media. It is not a consumer chatbot or a media generator, and self-hosting still requires capable NVIDIA hardware and production engineering.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Analyze long documents, charts, tables, screenshots, and scanned visual layouts in a shared context.
Connect what was said with what appeared on screen for meeting, training, media, and monitoring workflows.
Interpret graphical interfaces and screen state as the perception layer inside a broader agent.
Transcribe supported audio with word-level timestamps while keeping surrounding text or visual context available.
Use downloadable checkpoints when a team needs to operate a multimodal model within its own infrastructure.
Capabilities
Processes video, audio, images, and text in one model instead of requiring a separate perception model for each modality.
Supports up to 256K tokens for long documents and mixed-media reasoning.
The 31B architecture activates about 3B parameters per token to reduce inference work relative to a dense model of similar total size.
Reasoning is enabled by default, while a non-thinking instruct mode is available for shorter general tasks and transcription.
Supports JSON output, tool calling, and text responses for use inside larger automated workflows.
NVIDIA publishes BF16, FP8, and NVFP4 checkpoints for different memory, accuracy, and throughput tradeoffs.
Process
Step 1
Define whether the system needs document OCR, audio-video analysis, transcription, GUI perception, or a combination.
Step 2
Plan around the model card's supported formats, English-only scope, two-minute video guidance, one-hour audio limit, and 256K context.
Step 3
Test prompts, schemas, latency, and quality with NVIDIA's prototype API or another supported hosted provider.
Step 4
Choose BF16, FP8, or NVFP4 and a supported runtime such as vLLM, TensorRT-LLM, SGLang, llama.cpp, or Ollama.
Step 5
Measure extraction accuracy, transcription errors, hallucinations, latency, and cost using representative production inputs.
Step 6
Enforce input rights, protect sensitive media, validate tool calls, and monitor output quality before production use.
Cost
The downloadable model weights do not carry a separate per-token fee, but use is governed by NVIDIA's Open Model Agreement. NVIDIA offers a free hosted endpoint for prototyping; production endpoint, partner, GPU, storage, and operations costs depend on the deployment.
No model usage fee listed
Download BF16, FP8, or NVFP4 checkpoints and run them on infrastructure you control.
Free endpoint
A hosted NVIDIA NIM endpoint is available for development and prototyping.
Varies
Deploy through a partner endpoint, NVIDIA NIM, or self-managed GPU infrastructure.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Consumer
Choose Qwen3.5-Omni when multilingual omni-modal coverage is more important than NVIDIA's deployment stack.
Explore Qwen3.5-Omni →Consumer
Consider Gemini 3 when a managed frontier model is preferable to operating open checkpoints.
Explore Gemini 3 →Coding
Evaluate Molmo for an alternative open multimodal model focused on visual understanding.
Explore Molmo by Ai2 →Agents
Use Gemini 2.5 Computer Use for a specialized managed model aimed at browser and interface interaction.
Explore Gemini Computer Use →Questions
It is NVIDIA's open-weight multimodal reasoning model for understanding text, images, audio, video, documents, and graphical interfaces.
NVIDIA releases downloadable model weights and calls the model open, but use is governed by the NVIDIA Open Model Agreement. Review that agreement rather than assuming a standard permissive open-source license.
Yes. NVIDIA's official model card says the model is available for commercial use under the governing agreement.
NVIDIA lists one H100 80GB as the BF16 minimum, one L40S 48GB for FP8, and one RTX 5090 32GB for NVFP4. Recommended and production requirements vary with concurrency and workload.
No. It accepts those modalities as input but produces text-based output, including JSON, tool calls, and transcription timestamps.
The model card lists a 256K-token maximum context, video up to two minutes under its sampling guidance, and audio files up to one hour.
NVIDIA lists a free hosted endpoint for prototyping. Trial terms and limits apply, while production hosting and infrastructure have separate costs.
Bottom line
Nemotron 3 Nano Omni is compelling for teams that need one deployable perception model across documents, screens, audio, and video. The open checkpoints, structured outputs, 256K context, and multiple precision formats make it unusually flexible for enterprise agent architecture. Its English-only scope, short-video guidance, substantial GPU requirements, and text-only output mean teams should benchmark it against their exact workload before standardizing on it.
Visit Nemotron 3 Nano Omni website ↗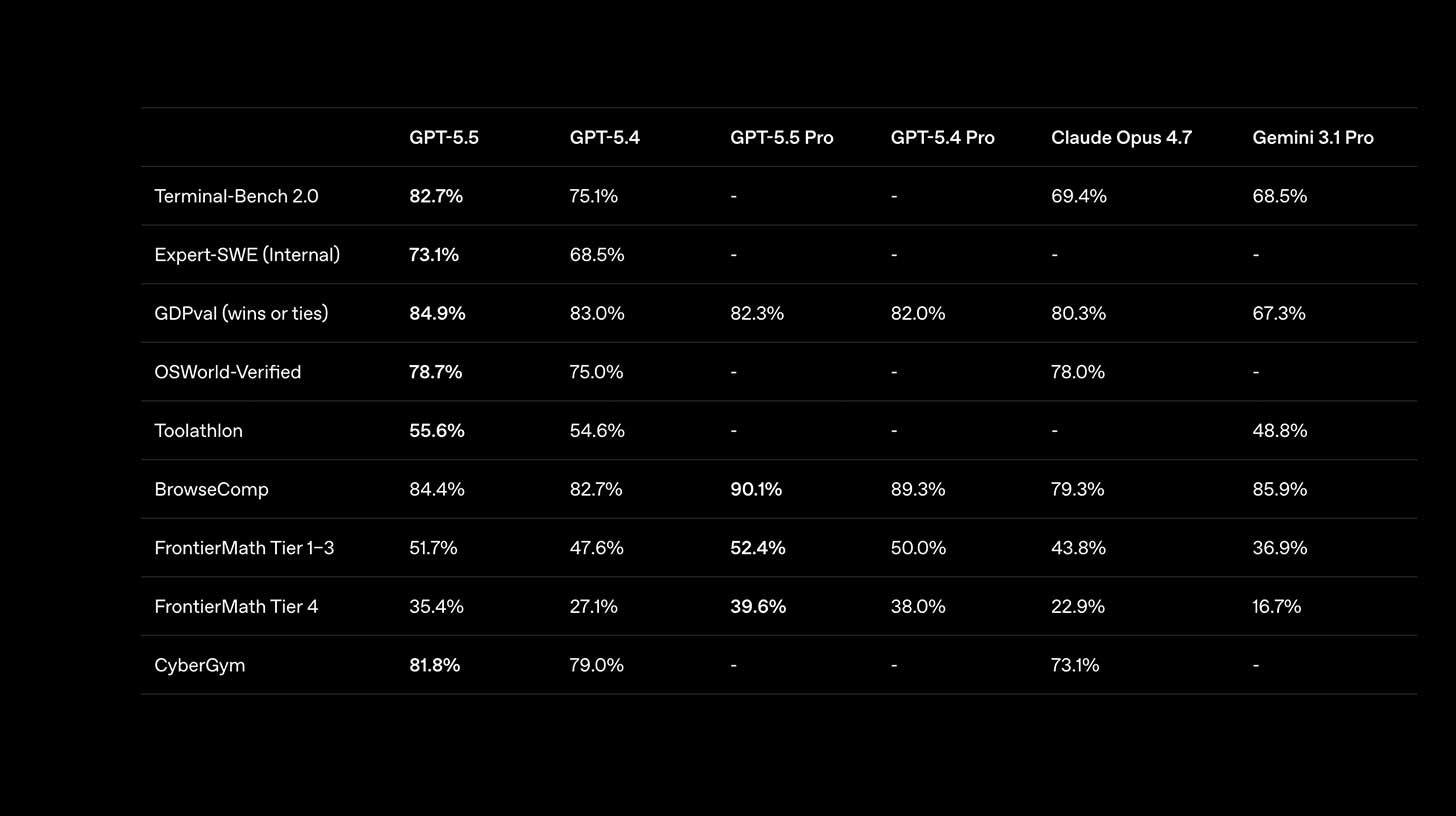

GPT-5.5 - OpenAI's new frontier flagship model for agentic coding and computer use

MiMo-V2.5-Pro - Xiaomi's powerful open-source model that excels in agentic and long-horizon tasks
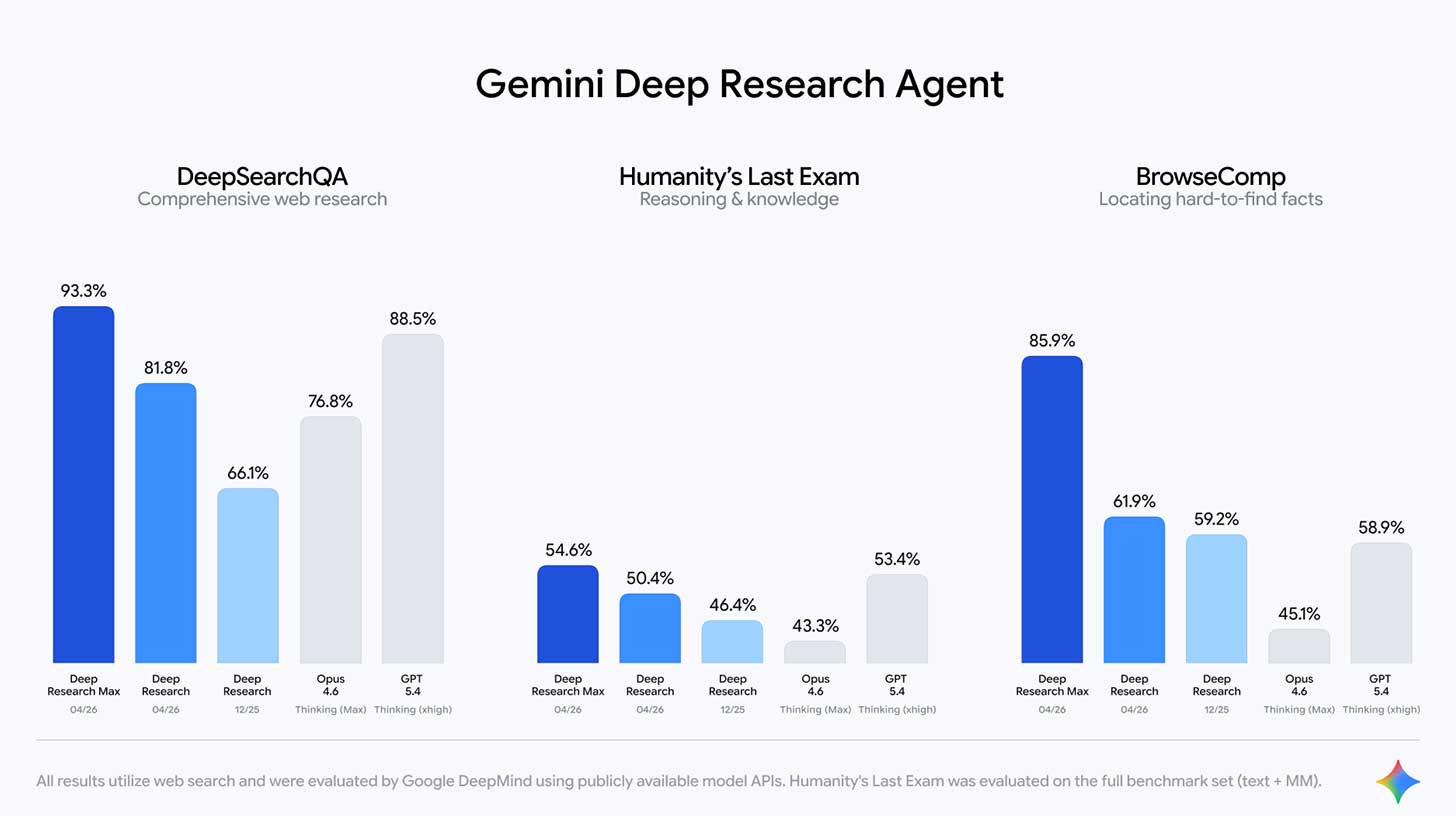
Deep Research Max - Google DeepMind's Gemini 3.1 Pro-powered autonomous research agent with MCP and native charts

Grok 4.3 - xAI’s latest model release with strong cost efficiency, instruction following, and domain-specific performance

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.

Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.

To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.

Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.

Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.