Multilingual voice agents
Build assistants that can listen, speak, see an image or camera frame and call application tools within the same experience.
Independent tool overview
Qwen3.5-Omni is Alibaba's hosted multimodal model family for applications that need to understand text, images, audio and video within one conversation and respond with text or synthesized speech.
Visit the official Qwen3.5-Omni site ↗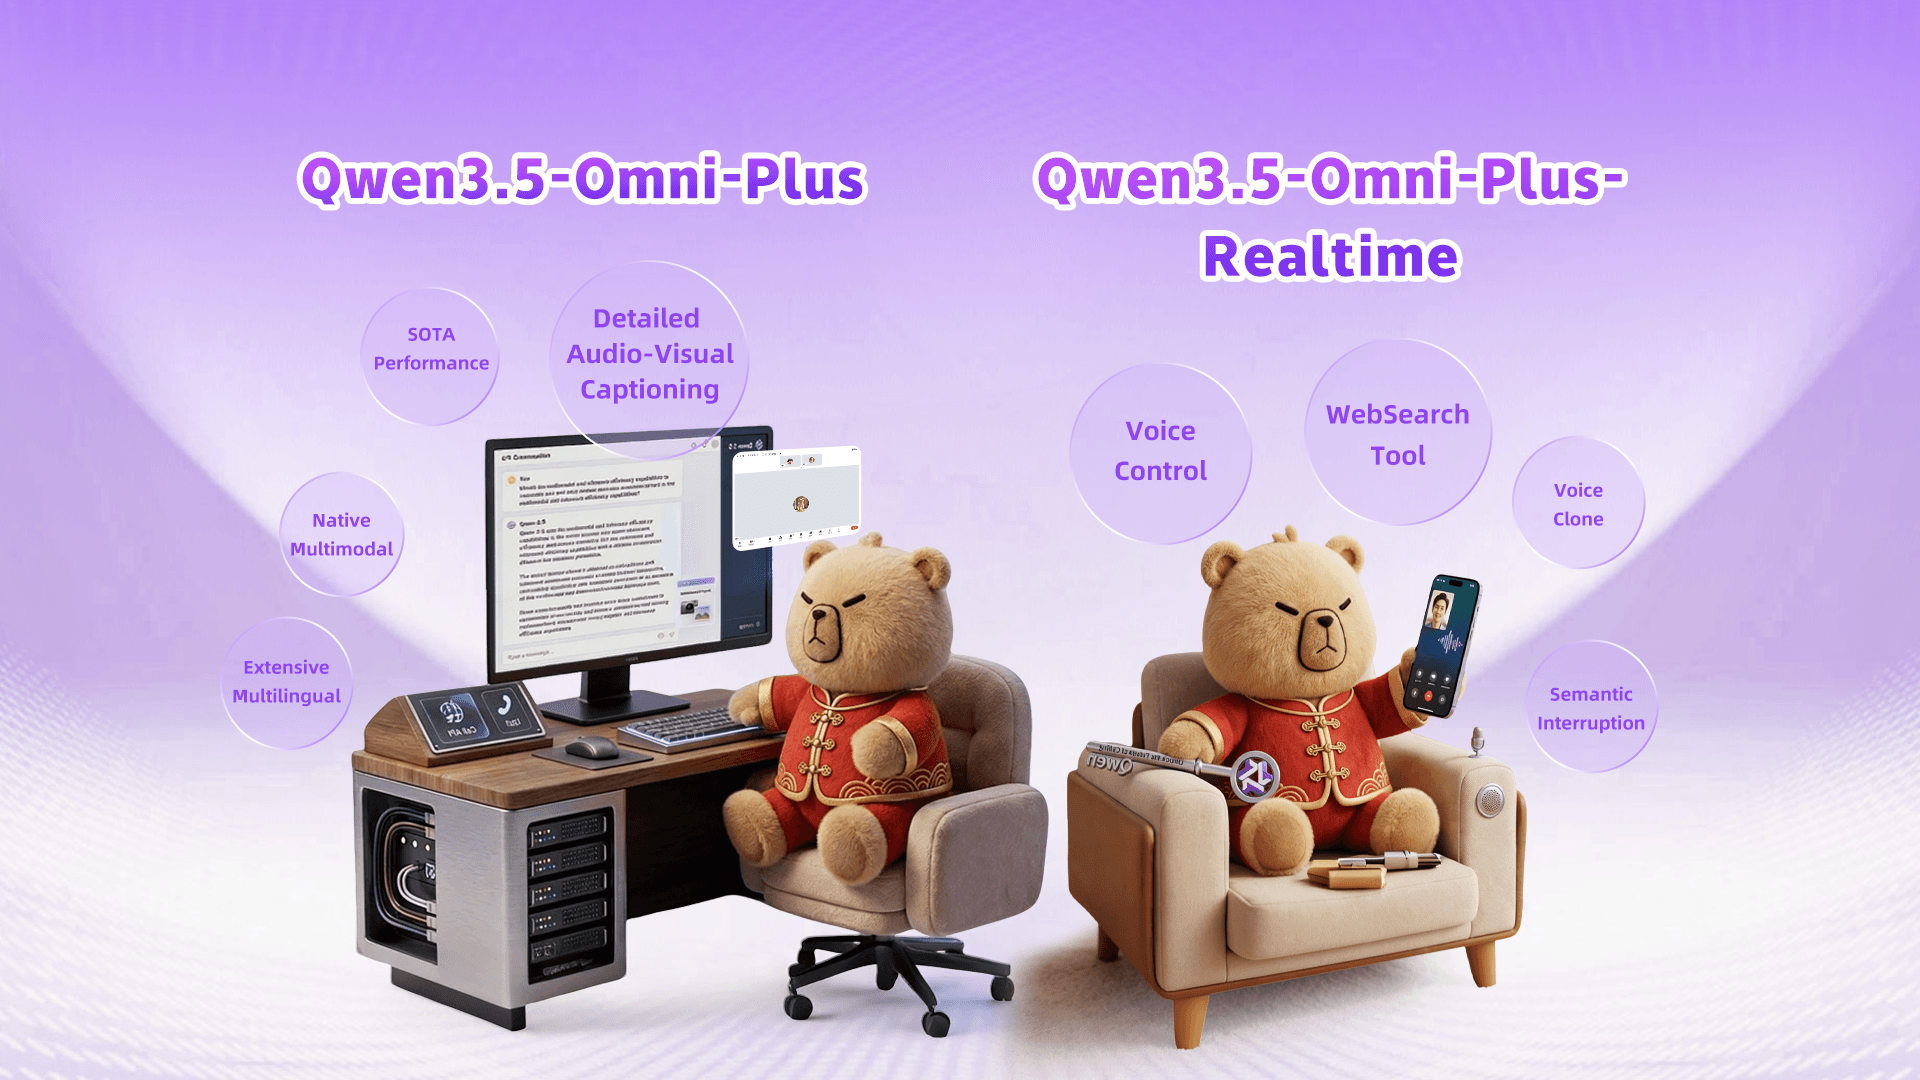
Overview
Qwen3.5-Omni combines visual, audio, video and language understanding in one hosted model family. The standard Plus and Flash APIs suit asynchronous analysis and speech generation, while separate Realtime variants are designed for low-latency voice and camera experiences.
Its broad modality support makes it useful for multilingual assistants, media analysis and accessibility workflows, but teams should evaluate the exact endpoint they plan to ship. Plus, Flash and Realtime differ in price, latency and supported tools.
Qwen3.5-Omni should not be confused with the older Qwen3-Omni open-weight release. Qwen3.5-Omni is currently documented as a hosted Model Studio and QwenCloud API; do not assume the older model's Apache 2.0 license applies.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Build assistants that can listen, speak, see an image or camera frame and call application tools within the same experience.
Create transcripts, scene descriptions, speaker-aware summaries and searchable metadata from long-form media.
Combine screen, camera, voice and text context for support, training, accessibility or creative applications.
Capabilities
Processes text, images, audio and video without requiring a separate model for every input type.
Can return text alone or stream text with generated audio using supported voices and endpoints.
Official materials describe more than 10 hours of audio and more than 400 seconds of 720p video at one frame per second for supported workflows.
Dedicated Plus and Flash Realtime models support low-latency speech-to-speech and audio-visual interactions.
Supported HTTP and WebSocket configurations can use web search, while function-calling availability depends on the endpoint.
Supports multilingual speech output and expressive controls; voice-cloning availability and consent requirements should be checked before use.
Process
Step 1
Select Plus, Flash or Realtime based on whether accuracy, price or conversational latency matters most.
Step 2
Set input limits, retention rules and consent requirements before sending private recordings, screens or voices.
Step 3
Test the languages, accents, noise levels, camera conditions and media lengths your users will actually provide.
Step 4
Monitor token growth, tool calls, latency and failure cases, and provide a human or text fallback for critical workflows.
Cost
Qwen3.5-Omni is metered by modality. Current international QwenCloud rates differ for text/image/video, audio and speech output, and multi-turn realtime sessions can rebill retained conversation context. Alibaba Cloud region and deployment pricing may vary.
$1.40–$44 per 1M tokens
Higher-capability hosted model with modality-specific rates.
$0.40–$11.90 per 1M tokens
Lower-cost hosted variant with the same broad modality categories.
From $7.014 per hour
Dedicated Alibaba Cloud deployment option for stable throughput.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Business Operations
Consider it for Google's low-latency native audio and video agent stack.
Explore Gemini 3.1 Flash Live →Miscellaneous
Consider it for OpenAI-based realtime voice agents, tool use and interruption handling.
Explore GPT-Realtime-2 →Miscellaneous
Consider it when accurate live or batch transcription matters more than full multimodal generation.
Explore Voxtral Transcribe 2 →Questions
Qwen3.5-Omni is currently documented as a hosted API family. The older Qwen3-Omni release has open weights under Apache 2.0, but that license should not be assumed to cover Qwen3.5-Omni.
Supported endpoints accept text, images, audio and video and can return text or synthesized speech. Realtime variants are available for interactive voice and camera experiences.
International QwenCloud pricing starts at $1.40 per million text, image or video input tokens for Plus and $0.40 for Flash. Audio input and audio output cost more, and regional Alibaba Cloud rates can differ.
Supported HTTP configurations can call functions. Some realtime WebSocket configurations do not, so verify the capability table for the exact model ID before designing an agent workflow.
Official materials describe more than 400 seconds of 720p video at one frame per second for supported workflows. Sampling and endpoint frame limits mean teams should test scene-level recall on their own content.
Bottom line
Qwen3.5-Omni is a strong hosted option when one application needs multilingual speech, visual context and media understanding together. Its practical value depends on selecting the right Plus, Flash or Realtime endpoint and controlling modality-specific costs, privacy and long-context behavior.
Visit Qwen3.5-Omni website ↗
Cohere Transcribe- SOTA, free open-source speech recognition model

Trinity-Large-Thinking - Arcee AI's new open-weight frontier reasoning model for long-horizon agents

MiniMax M2.7 - MiniMax's new 'self-evolving' model with strong coding and agentic benchmarks

LFM2.5-350M - Liquid AI's 350M-parameter edge model built for tool use and on-device agents

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.