Coding agents
Use M2.7 for repository work, debugging, refactoring, tool calls, and other multi-step software-engineering tasks.
Independent tool overview
MiniMax M2.7 is an open-weight text model built for coding, tool use, and long-running agent workflows. It remains available at a low API price, although MiniMax M3 is now the newer, multimodal model with a much larger context window.
Visit the official Minimax M2.7 site ↗
Overview
MiniMax released M2.7 in March 2026 as a 229-billion-parameter open-weight model focused on software engineering, office work, tool use, and multi-agent workflows. The hosted API supports a 204,800-token combined input-and-output window, while MiniMax publishes model weights for teams that want to run it on their own infrastructure.
MiniMax calls M2.7 its first model to participate deeply in its own evolution. That does not mean the public model autonomously retrains itself. MiniMax describes internal experiments in which M2.7 built and revised agent harnesses, skills, memory systems, evaluation loops, and research workflows while human researchers retained control over goals and critical decisions.
M2.7 is no longer MiniMax's newest M-series model. MiniMax M3 adds native image and video understanding, computer use, and a 1-million-token context window. M2.7 still makes sense when a text-only coding or agent workload values its established integrations and lower-cost standard or high-speed API options.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Use M2.7 for repository work, debugging, refactoring, tool calls, and other multi-step software-engineering tasks.
Its focus on skills, tools, memory, and role consistency suits teams building text-based autonomous or multi-agent workflows.
The standard hosted model offers low per-token pricing for applications that do not need M3's multimodal input or 1M-token context.
Published weights and deployment guidance support teams with enough infrastructure to run and evaluate the model themselves.
Capabilities
M2.7 is tuned for multi-step work involving tools, skills, memory, search, and complex execution environments.
MiniMax reports gains across debugging, security analysis, machine learning, mobile development, repository-level generation, and terminal tasks. Treat its benchmark comparisons as vendor-reported results.
The model can work through document, spreadsheet, and presentation tasks when connected to an agent harness with the relevant files and tools.
MiniMax trained the model for role adherence and collaboration in multi-agent setups, though reliability still depends on the surrounding orchestration and evaluation.
The hosted service accepts Anthropic-style and OpenAI-style requests; MiniMax recommends its Anthropic-compatible endpoint for thinking blocks and interleaved reasoning.
The standard endpoint is documented at roughly 60 output tokens per second and the high-speed version at roughly 100 tokens per second.
The official 229B-parameter checkpoint is available through MiniMax's Hugging Face organization, with guidance for SGLang, vLLM, Transformers, ModelScope, and NVIDIA NIM.
Process
Step 1
Use MiniMax's API for the quickest setup, or assess the hardware and operational cost of serving the 229B-parameter checkpoint yourself.
Step 2
Select standard M2.7 for lowest cost or M2.7-highspeed when output latency matters more than token price.
Step 3
Give the model only the file, shell, browser, database, or MCP permissions required for the task, with approval gates for consequential actions.
Step 4
Test repository tasks, tool-call accuracy, long-context behavior, latency, and cost on your own workload instead of relying only on vendor benchmarks.
Step 5
Move to M3 when you need native image or video input, computer use, or a context window beyond 204,800 tokens.
Cost
MiniMax sells M2.7 through pay-as-you-go API billing and separate subscription-style token plans. The prices below are the published pay-as-you-go API rates; self-hosting has no per-token vendor charge but requires substantial compute and operations.
$0.30 input / $1.20 output per 1M tokens
Standard hosted text model, documented at approximately 60 output tokens per second.
$0.60 input / $2.40 output per 1M tokens
Faster hosted variant with the same stated model performance and approximately 100 output tokens per second.
No per-token MiniMax API fee
Download the official checkpoint and run it on compatible infrastructure.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Consumer
Choose MiniMax's newer model for native multimodal input, computer use, and a 1M-token context window.
Explore MiniMax M3 →Consumer
Compare another current open-weight model built for coding, agents, long context, and multimodal tasks.
Explore GLM-5.3 →Consumer
Consider Anthropic's closed model when premium coding and agent performance matters more than open weights or low token cost.
Explore Claude Opus 4.6 →Questions
MiniMax M2.7 is a 229B-parameter open-weight text model designed for coding, tool use, office workflows, and multi-agent systems. It can be used through MiniMax's hosted API, MiniMax Agent, or self-hosted weights.
Yes. MiniMax's API documentation still lists M2.7 and M2.7-highspeed as available models. MiniMax M3 is now the latest M-series model, while M2.7 remains a lower-cost text-only option.
MiniMax uses that phrase for internal workflows where M2.7 helped build and improve agent harnesses, skills, memory, and evaluation loops. The public model does not independently retrain its weights while you use it, and human researchers still directed critical decisions in the examples MiniMax published.
As of August 29, 2026, standard M2.7 costs $0.30 per million input tokens and $1.20 per million output tokens. M2.7-highspeed costs $0.60 input and $2.40 output per million tokens. Prompt caching has separate read and write rates.
MiniMax documents a 204,800-token total context window for both the standard and high-speed variants. That maximum includes input and output tokens together.
MiniMax publishes the model weights and deployment instructions, so open-weight is the most precise description. Review the license attached to the official model repository before assuming unrestricted open-source or commercial rights.
Use M2.7 when low-cost text generation, coding, or tool use is the priority. Use M3 when you need image or video understanding, desktop computer use, a 1M-token context window, or MiniMax's newest model generation.
Bottom line
MiniMax M2.7 remains an appealing low-cost model for text-based coding and agent systems, especially for teams that value open weights and familiar API formats. Its 'self-evolution' story is best understood as agent-harness optimization under human direction, not autonomous retraining. New projects should compare it directly with M3, because M3 is now the current MiniMax generation and adds capabilities M2.7 cannot provide.
Visit Minimax M2.7 website ↗
GLM-5-Turbo - Z AI's high-speed agentic model built specifically for OpenClaw
Cohere Transcribe- SOTA, free open-source speech recognition model
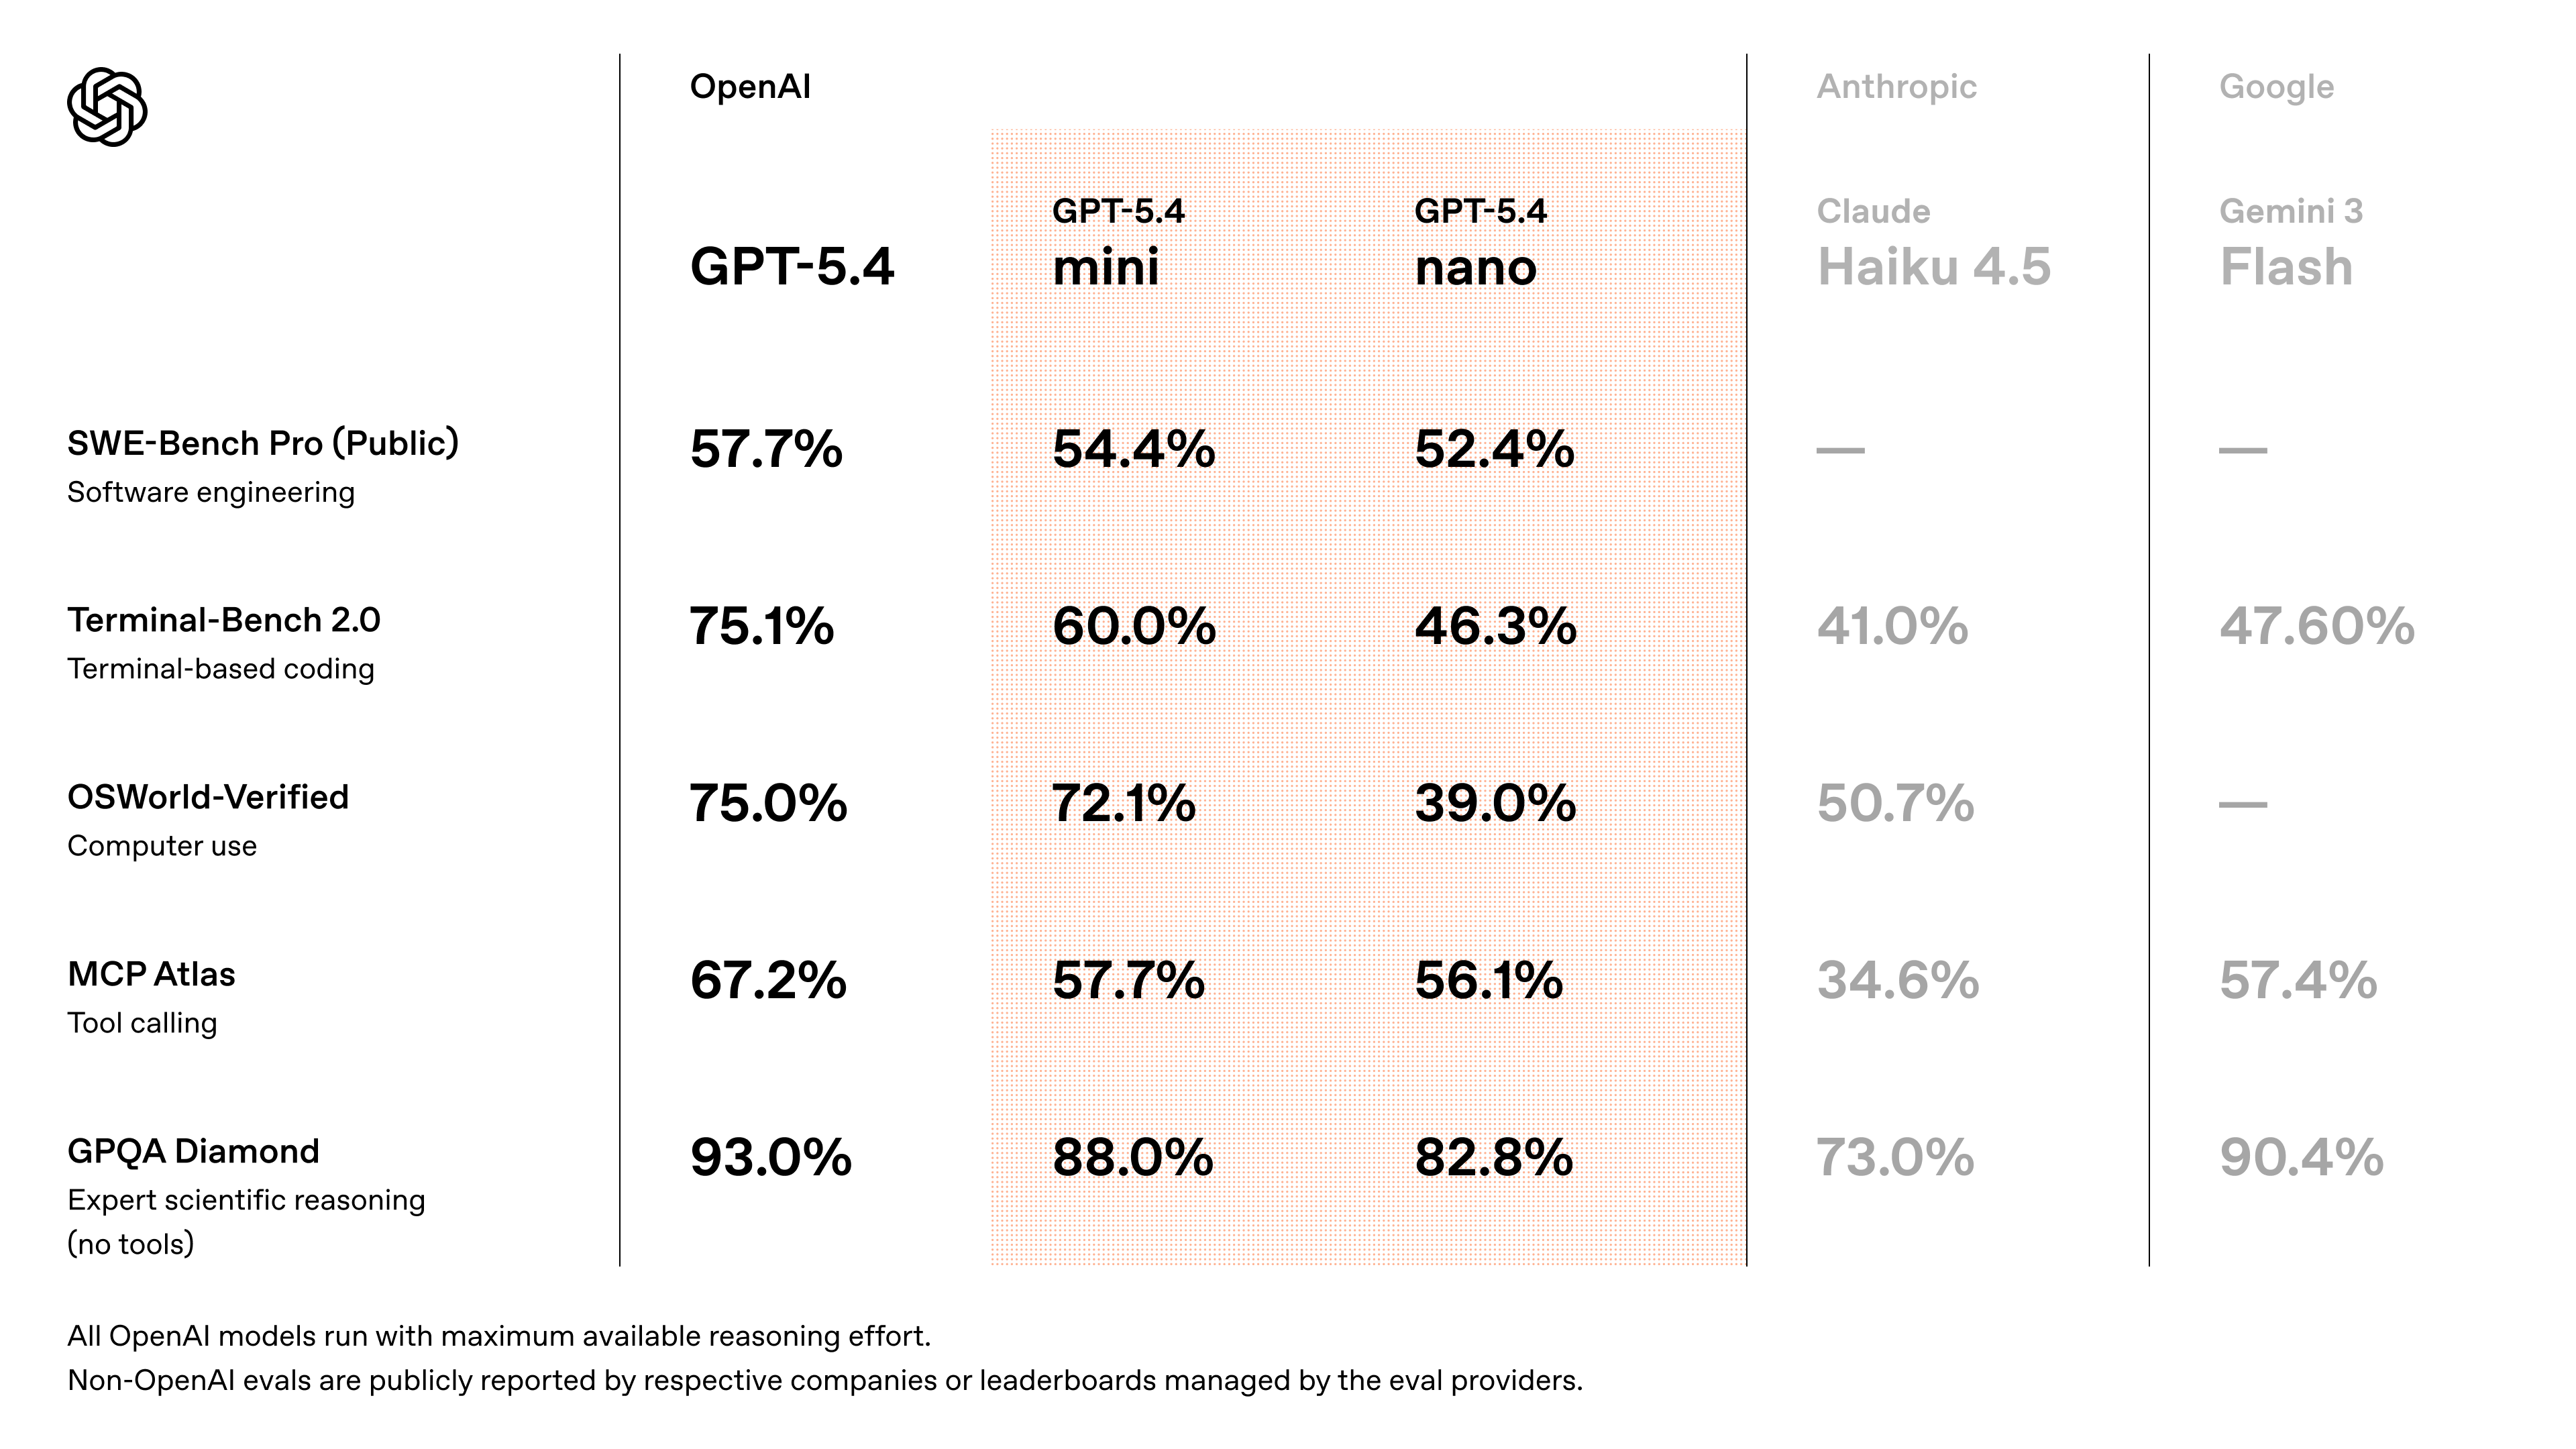
GPT-5.4 mini & nano - OpenAI's fast, cheap small models built for coding agents and subagent workflows

Qwen 3.5 Omni - Alibaba's native omnimodal model with text, image, audio, and video understanding across 113 languages

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.