Production AI teams
Engineers who need request-level visibility into latency, cost, errors and model behavior.
Independent tool overview
Helicone is an open-source LLM observability platform and AI gateway for logging model requests, tracking cost and latency, analyzing users and sessions, managing prompts, and routing traffic across providers.
Visit the official Helicone site ↗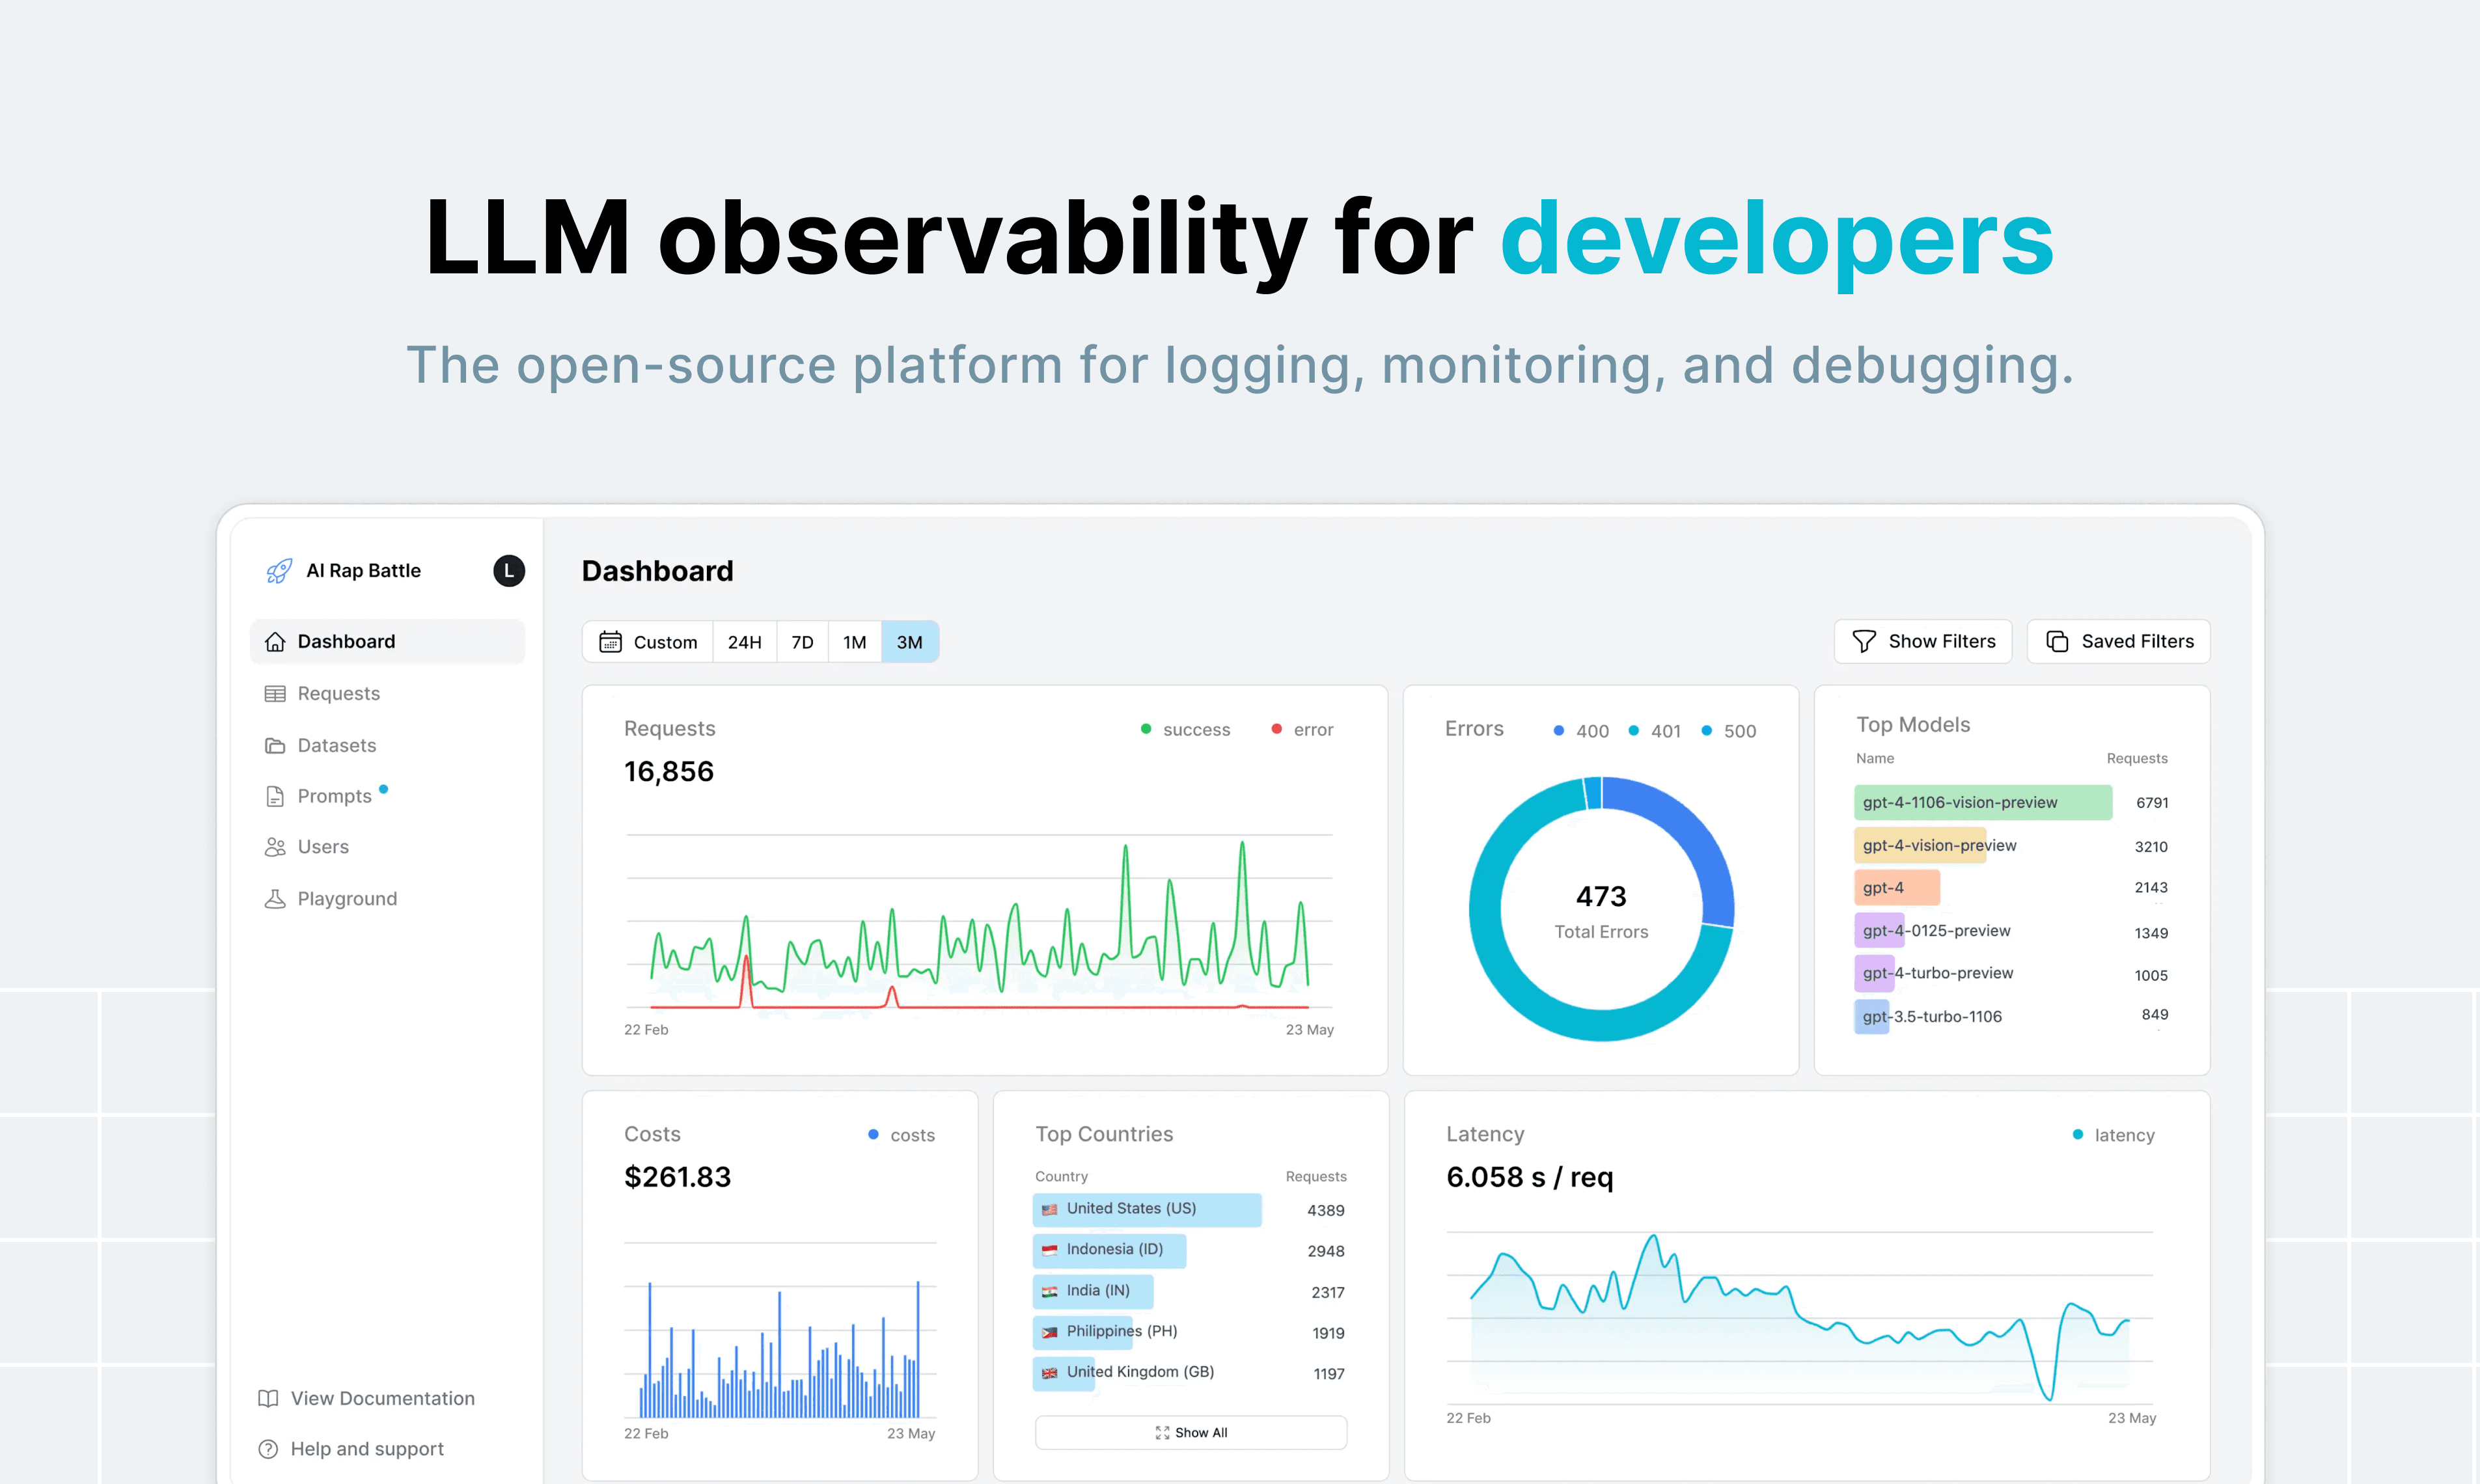
Overview
Helicone sits between an AI application and its model providers, or accepts asynchronous logs, to give engineering teams one place to inspect requests, costs, latency, errors and usage patterns. Its OpenAI-compatible gateway also provides access to more than 100 models with routing, caching and automatic fallbacks.
The hosted product combines monitoring with prompt versioning, a playground, scores, datasets, webhooks, alerts and reports. Developers can attach user, session and custom-property metadata so a raw model call becomes traceable to a customer, workflow or release.
Helicone is also open source and publishes self-hosting options for teams that need greater data control. Self-hosting shifts deployment, upgrades, storage, security and reliability to the buyer, while the managed Team and Enterprise plans package higher limits, compliance features and support.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Engineers who need request-level visibility into latency, cost, errors and model behavior.
Teams that want one OpenAI-compatible API with routing, caching and provider fallbacks.
Organizations willing to operate the open-source stack inside their own infrastructure.
Capabilities
Inspect prompts, responses, token usage, model cost, latency, status and custom metadata in a searchable request log.
Group multi-step calls into sessions and connect model activity to users for product-level analysis.
Use an OpenAI-compatible endpoint to access more than 100 models with routing, automatic fallbacks, caching and rate limits.
Version prompts, use typed variables, test them in the playground and deploy prompt changes through an identifier.
Attach feedback or evaluator scores, then curate logged examples for evaluation, analysis or fine-tuning workflows.
Paid plans add alerts, reports and Helicone Query Language for operational analysis.
Run the platform with Docker or Kubernetes when data sovereignty or infrastructure control outweighs managed convenience.
Process
Step 1
Use the Helicone AI Gateway, a provider-specific proxy or a manual logger according to latency, provider and data-routing requirements.
Step 2
Tag requests with user IDs, session IDs, prompt IDs, environment and application properties so logs can answer product questions.
Step 3
Filter requests and dashboards for failures, slow calls, costly models, outlier users and problematic prompt versions.
Step 4
Collect feedback and scores, curate datasets, test prompt changes and compare outcomes before wider release.
Step 5
Apply gateway caching, rate limits, routing and fallbacks, then monitor whether those policies improve reliability without masking quality problems.
Cost
Managed plans include a subscription tier plus usage-based charges where stated. All listed plans include 10,000 monthly requests; paid usage, storage and model-provider charges can increase the total. Self-hosting avoids a managed-plan dependency but creates infrastructure and operations costs.
Free
A limited managed workspace for small projects.
$79 per month + usage
A managed plan for growing teams.
$799 per month + usage
Higher limits, compliance and support for scaling companies.
Contact sales
Custom commercial and deployment terms.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Miscellaneous
Choose Mistral Studio when managed model development, evaluation and deployment within Mistral's platform are the priority.
Explore Mistral Studio →Coding
Choose Together AI when hosted inference and model customization matter more than provider-neutral observability.
Explore Together AI →Coding
Choose Google AI Studio for a simpler Gemini-focused prototyping environment rather than a production-wide observability layer.
Explore Google AI Studio →Questions
Helicone records LLM request and response data plus metrics such as tokens, cost, latency, status, model, users, sessions and custom properties. What is visible depends on the integration and logging configuration.
Not necessarily. You can use its gateway to access supported models or route calls through provider-specific proxies while retaining your provider relationship. Model usage charges remain separate.
Yes. Helicone publishes its platform code and documents Docker, Kubernetes, manual and cloud self-hosting options.
Helicone documents controls such as omitting logs and a key vault, but teams should test the exact behavior and design their own redaction, retention and access policies before sending sensitive production traffic.
The current Hobby plan lists 10,000 requests per month, 1 GB of storage, one seat, one organization, seven days of retention and an ingestion limit of 10 logs per minute.
The Helicone subscription and observability usage are separate from the underlying model cost. Gateway or provider billing arrangements determine how model usage itself is paid.
Bottom line
Helicone is a strong fit for teams that want fast, provider-flexible LLM monitoring and gateway controls without giving up a self-hosting path. The biggest decision is architectural: determine whether to put the managed gateway in the critical path or log asynchronously, then model the metered cost and treat prompt data as production-sensitive telemetry.
Visit Helicone website ↗
Generate apps using screenshots for inspiration.

Meta Llama Models: Llama models from meta offer open-source, state-of-the-art foundational models for research and deployment.

Multimodal language model for diverse applications.

Replit Agent: Is your ai coding companion for building, debugging, and deploying code directly in replit.

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.