Training and onboarding libraries
Create repeatable presenter-led modules and update scripts without asking the subject to return to a studio.
Independent tool overview
Avatar V is HeyGen's newest digital-twin model for creating a reusable on-camera version of a real person from a 15-second reference video. It learns the person's face, movement, gestures, and expressions, then carries that identity into new scripts, outfits, settings, camera angles, languages, and longer videos. Avatar IV still exists for single-photo and non-human avatars; Avatar V is the video-trained option for real people.
Visit the official Avatar V site ↗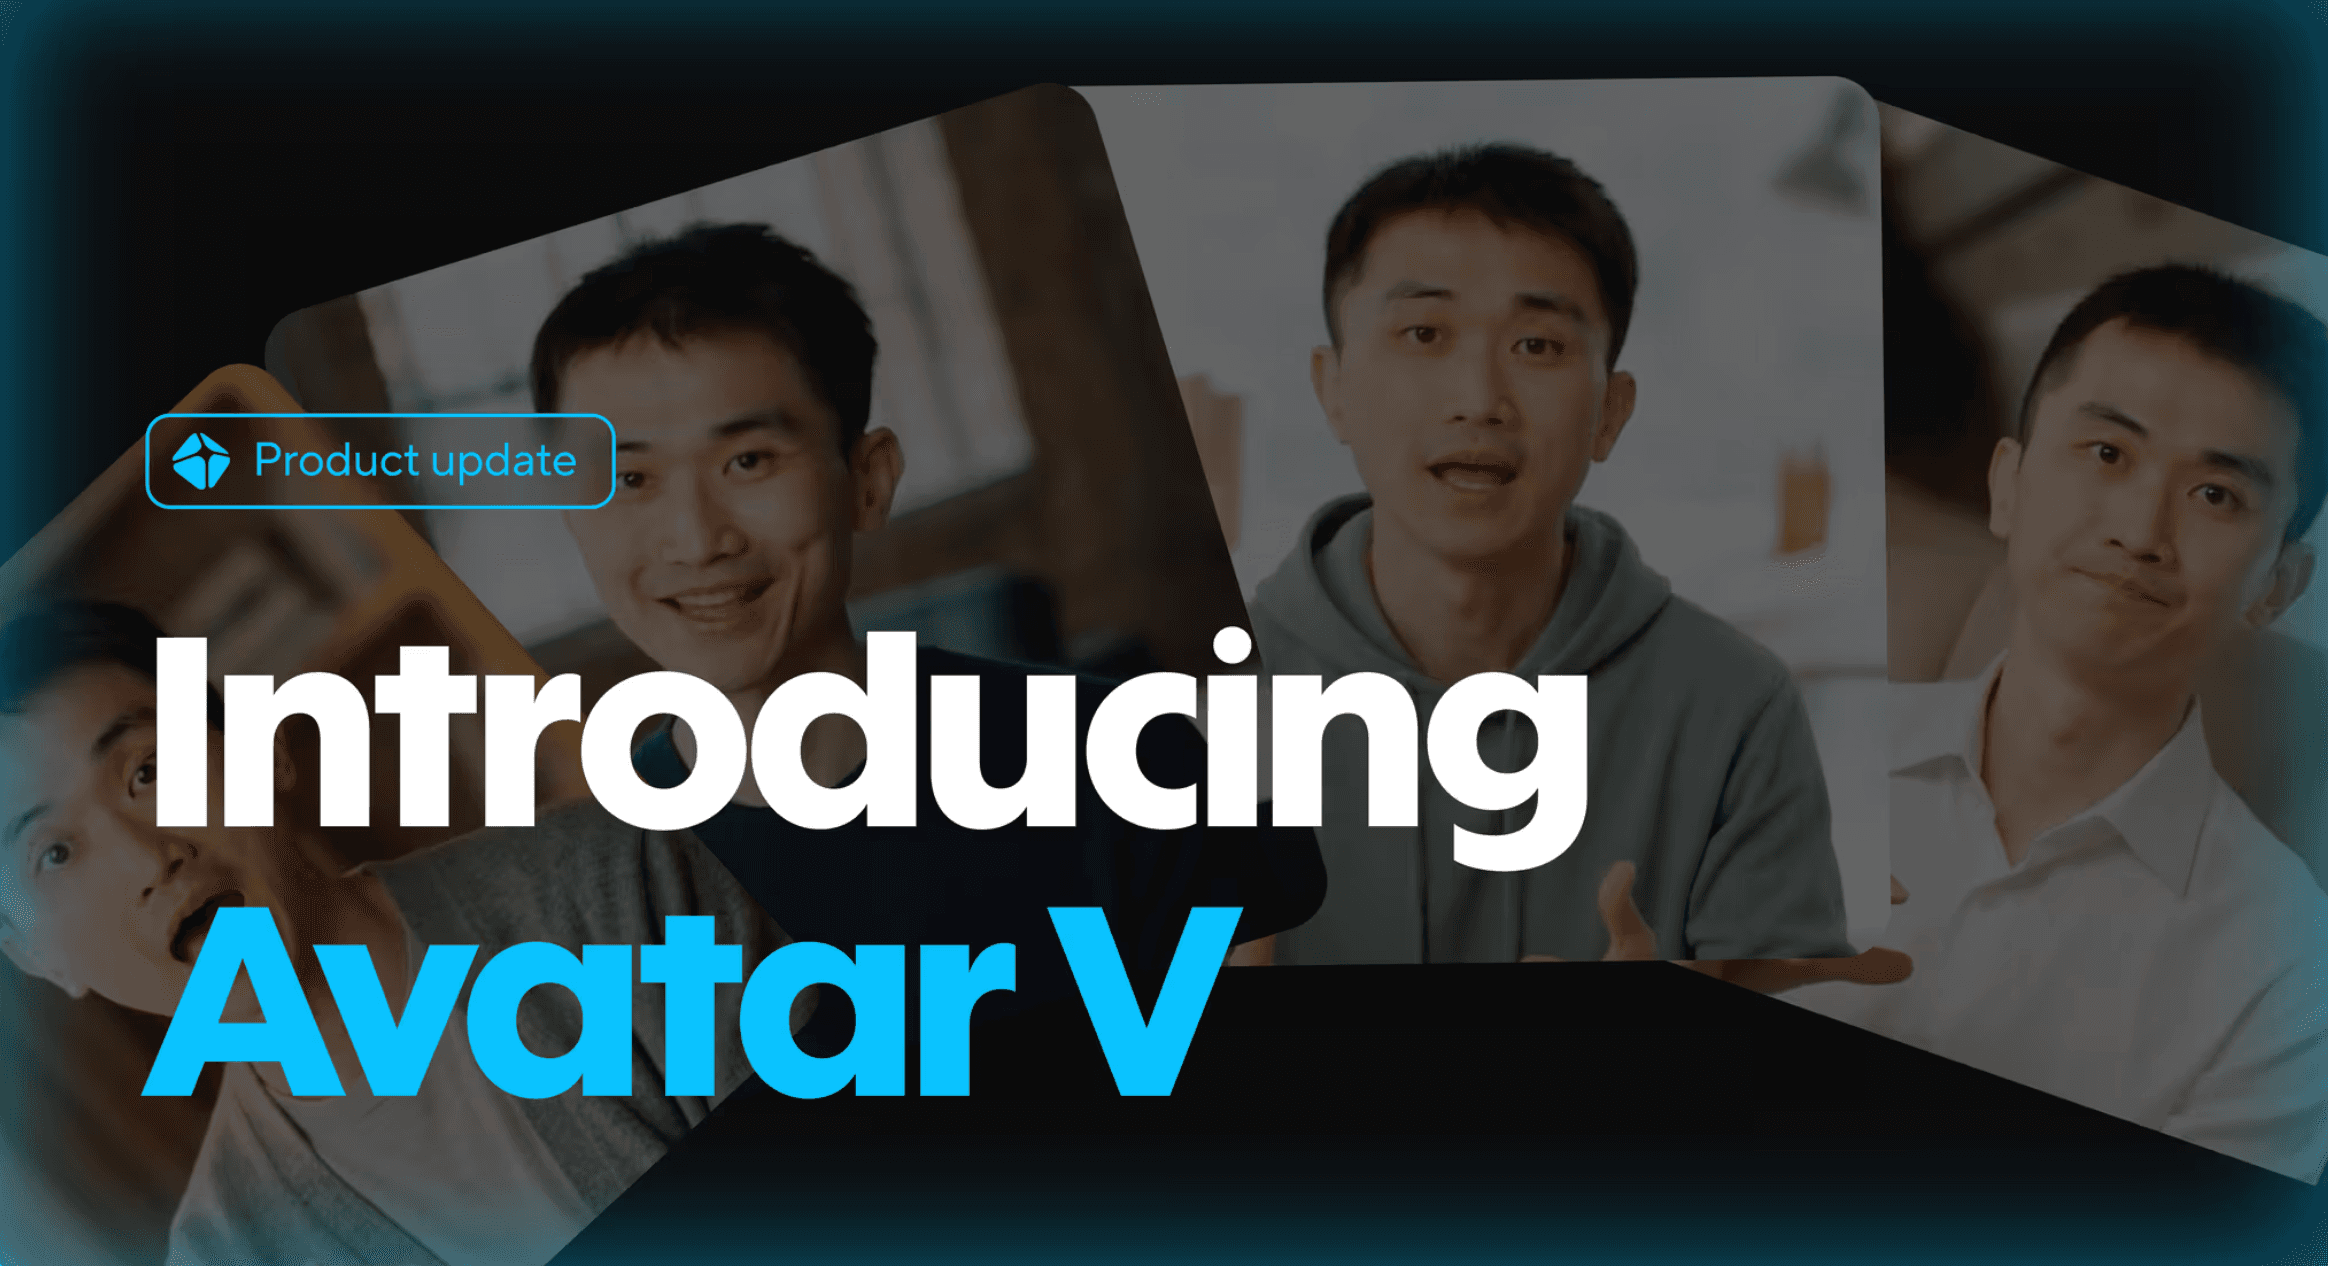
Overview
Avatar V is a model inside the broader HeyGen video platform, not a separate subscription. It is built for people who want to appear consistently in training, marketing, sales, localization, executive, or social videos without filming each version.
The model uses a short video context rather than Avatar IV's single-photo starting point. HeyGen says this lets it learn person-specific motion and maintain identity across scene changes, camera angles, different looks, and long-form output.
Avatar V currently works only with video-based Looks and is optimized for real human avatars. HeyGen recommends Avatar IV for photo-based Looks, cartoons, 2D or 3D characters, animals, and other non-human subjects.
The model uses HeyGen's shared credit pool at 48 credits per minute of Avatar V generation. A HeyGen plan may include many other unlimited or bundled video features, but Avatar V itself remains metered, so frequent or long-form use needs a credit budget.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Create repeatable presenter-led modules and update scripts without asking the subject to return to a studio.
Scale internal updates, announcements, thought leadership, and localized messages while keeping a recognizable spokesperson.
Produce personalized outreach, product walkthroughs, feature announcements, and customer education with the same digital presenter.
Reuse one approved digital twin across many languages while HeyGen handles speech, lip sync, and translated delivery.
Capabilities
Create the model from a short webcam video that captures the subject's appearance, motion, gestures, and expressive patterns.
The video-context architecture is designed to preserve the same person across longer runtimes, changing scenes, and multiple camera angles.
Apply the learned identity and movement to different approved photos, outfits, settings, backgrounds, and visual treatments.
Generate presenter motion that includes gestures, posture, facial expressions, eye contact, and lip sync rather than animating only the mouth.
HeyGen positions Avatar V for material such as courses, onboarding, and walkthroughs where appearance needs to remain stable beyond a short clip.
Use HeyGen's voice and localization tools to deliver avatar-led content in more than 175 languages and dialects.
Use Avatar V in HeyGen Studio, the homepage shortcut, or Video Agent; Video Agent selects it automatically for eligible real-human avatars.
Keep using Avatar IV for single-photo Looks and non-human, cartoon, 2D, or 3D characters that do not fit Avatar V's real-person workflow.
Process
Step 1
Confirm the person understands the intended uses, then have that same person complete HeyGen's live consent-video process.
Step 2
Capture a clear 15-second webcam clip with natural speech, visible facial detail, and the gestures you want the model to learn.
Step 3
Submit the reference and optional voice-clone setup, then review whether the trained identity actually resembles and moves like the subject.
Step 4
Select an approved appearance and setting, write the script, choose the language and voice, and assign Avatar V as the motion engine.
Step 5
Check lip sync, facial and hand artifacts, identity drift, pronunciation, factual accuracy, disclosure, and brand fit before distribution.
Cost
Avatar V is metered through HeyGen rather than sold on its own. HeyGen's current help center lists Avatar V Video Looks at 48 credits per generated minute. Current individual plans are Creator at $29 per month for 600 credits and Pro at $49 for 1,000 credits; Business is $149 per month for 1,500 credits, with extra seats at $20 each. Those pools also pay for other metered HeyGen features, so the available Avatar V minutes depend on the rest of the workflow. HeyGen's public plan table still names Avatar IV rather than publishing a distinct Avatar V allowance for each tier, so confirm access in the account before buying primarily for this model.
$0/month
A limited platform test; the public plan table explicitly includes Avatar IV but does not state a separate Avatar V allowance.
$29/month
The entry paid plan for individual creators using HeyGen's generative tools.
$49/month
Adds a larger credit pool, 4K output, and access to advanced models.
$149/month
For collaborative video programs with more digital twins and governance features.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Marketing
A stronger fit for governed training, learning, internal communications, and enterprise template workflows.
Explore Synthesia →Content Creator
Better suited to programmable personalized video and conversational digital-replica experiences.
Explore tavus →Content Creator
A creator-first alternative for mobile editing, AI twins, dubbing, and social-video production.
Explore Captions →Content Creator
Combines custom avatars with product interactions, social editing, and short multi-scene storytelling at a lower entry price.
Explore Argil →Questions
Avatar V is HeyGen's video-trained digital-twin model. It learns a real person's identity, gestures, expressions, and motion from a 15-second reference, then uses that performance style in new scripted videos.
Avatar IV can animate a single photo and works well for cartoon, 2D, 3D, animal, and other non-human characters. Avatar V starts with a video of a real person and is designed for stronger identity, motion, multi-angle, and long-form consistency.
Avatar V is part of HeyGen and currently costs 48 HeyGen credits per generated minute. HeyGen plans start free; paid individual plans currently start at $29 per month, but the public pricing table does not state Avatar V access separately for every tier.
That depends on the plan's credit pool and what other HeyGen features consume credits. At 48 credits per minute, 600 credits would cover at most about 12.5 minutes if used only for Avatar V, before any other metered work.
No. HeyGen says Avatar V is available only for video-based Looks. Use Avatar IV for a standalone photo or a non-human character.
Yes. HeyGen requires a separate consent video for each video-based Digital Twin, and the person in that video must match the person in the training footage.
HeyGen positions Avatar V for long-form stability, but account plan limits and available credits still govern practical duration. Long output should be reviewed in full because small artifacts can accumulate.
It can support business video, but teams need explicit scope-of-use permission, secure account access, approval controls, visible disclosure where required, and review of every generated statement and performance.
Bottom line
Avatar V is a meaningful HeyGen upgrade for organizations that want a real person's digital twin to remain recognizable across different scenes, Looks, languages, and longer videos. It is less suitable for one-off photo animation or fictional characters, where Avatar IV is still the intended engine. The biggest buying questions are not just visual realism: confirm plan access, model the 48-credit-per-minute cost, define the subject's consent in writing, secure the account, and treat every generated performance as material that still needs human approval.
Visit Avatar V website ↗

MAI Image 2 - Microsoft AI's image model with upgraded photorealism and creativity
HeyGen CLI - Agent-first tool for generating and shipping videos from the terminal

VOID - Neflix's open-source AI video editing model that erases objects while rewriting the physics associated with them

ERNIE-Image - Baidu's 8B open-weight text-to-image model that nears top rivals on benchmarks despite its small size

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.

Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.

To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.

Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.

Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.