Long-running agents
Handle repeated tool calls, result validation, formatting, and other execution-heavy steps.
Independent tool overview
NVIDIA Nemotron 3.5 Lightning is an open-weight 30B mixture-of-experts model with 3B active parameters, built for fast, high-volume execution inside long-running AI agents.
Visit the official Nemotron 3.5 Lightning site ↗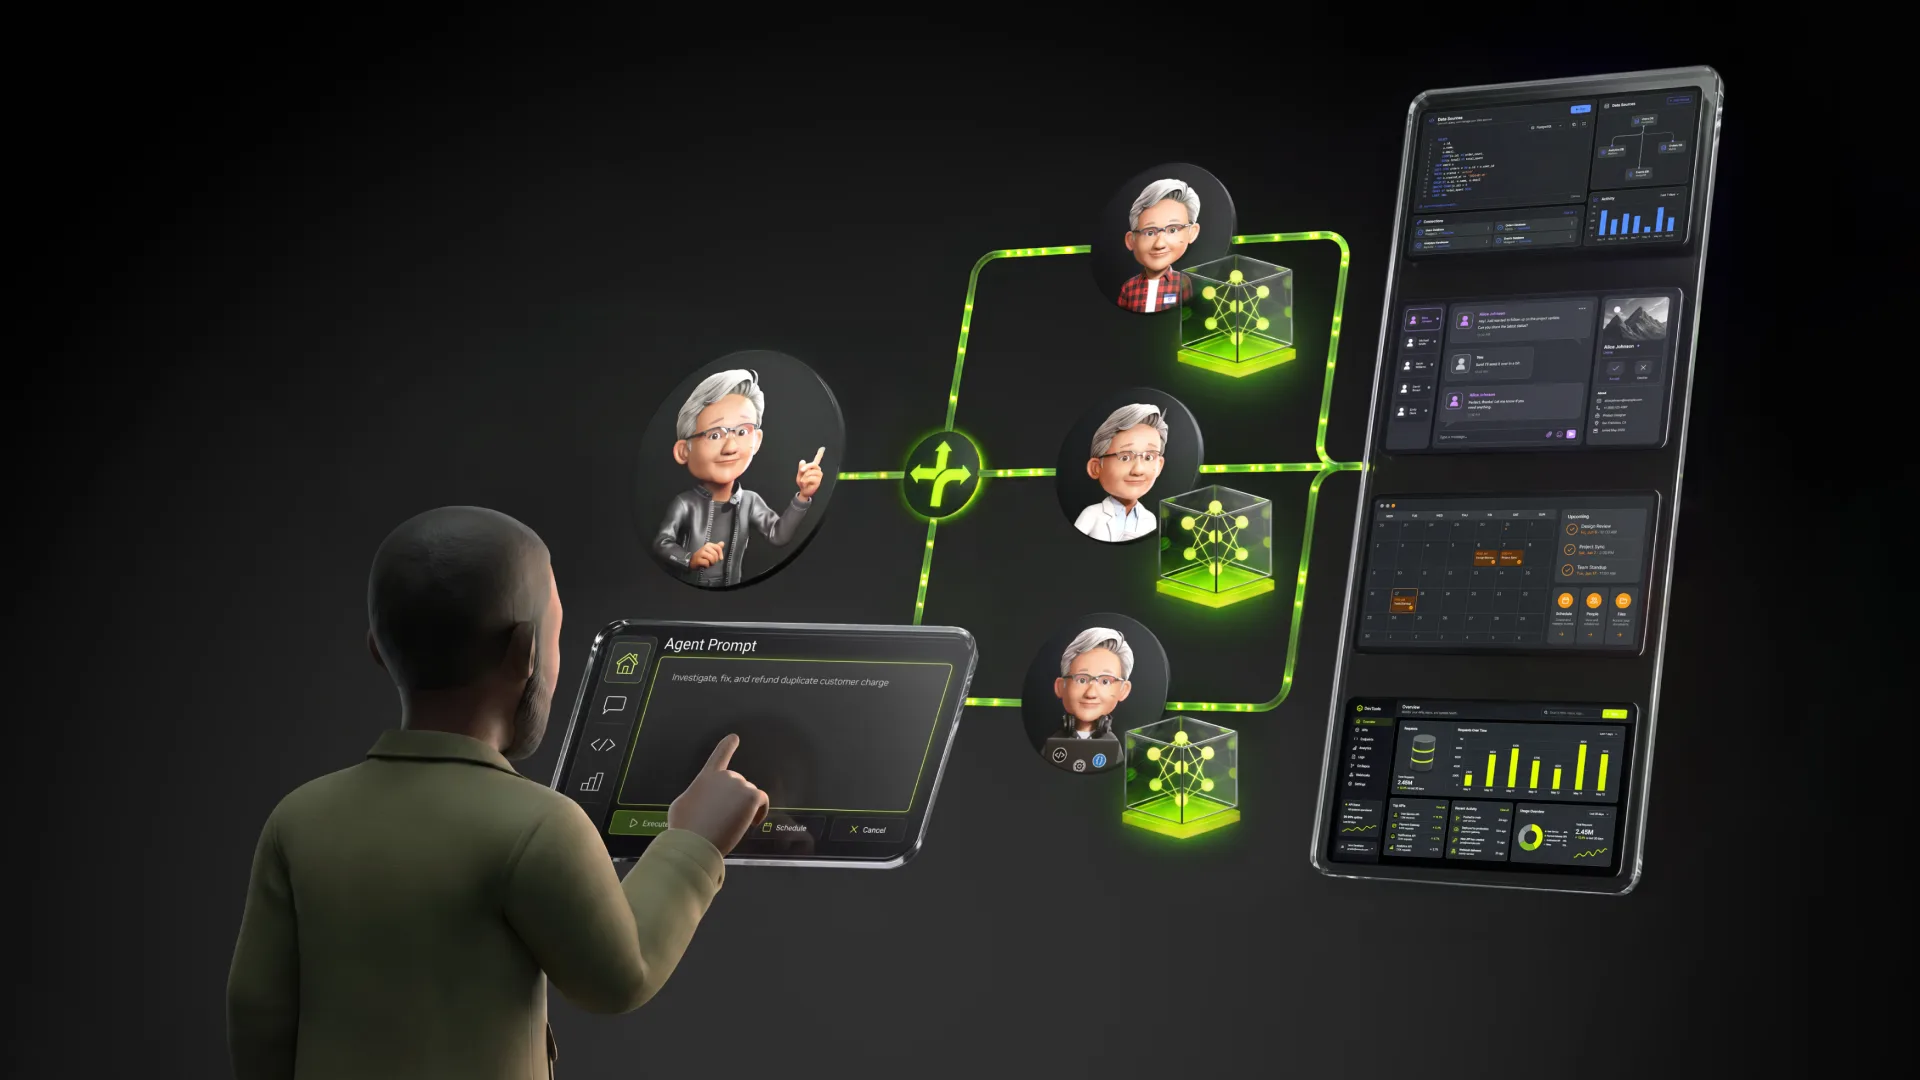
Overview
Nemotron 3.5 Lightning is the execution-focused member of NVIDIA's Nemotron family. Its hybrid Mamba-2, mixture-of-experts, and attention architecture activates about 3B of its 30B parameters per token, targeting lower latency for tool calls, validation, coding work, and delegated sub-agent tasks.
NVIDIA releases BF16 and NVFP4 checkpoints, speculative-decoding options, training data, and recipes under the OpenMDW 1.1 license. The model supports up to a 1 million-token context and can be served locally or in a data center using tools such as vLLM, SGLang, TensorRT-LLM, Ollama, llama.cpp, and LM Studio.
This is an infrastructure component, not a consumer chatbot. Teams need suitable NVIDIA hardware or a hosted endpoint, an agent harness, evaluation datasets, security controls, and routing logic that sends harder planning work to a more capable model when needed.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Handle repeated tool calls, result validation, formatting, and other execution-heavy steps.
Use a smaller local or hosted model for delegated tasks while reserving frontier models for planning.
Run open weights on controlled infrastructure when data locality and operational control matter.
Adapt the model to a narrow workflow with LoRA, supervised fine-tuning, or reinforcement learning.
Capabilities
Uses 30B total parameters while activating about 3B per token to improve serving efficiency.
Supports long prompts and agent histories on NVIDIA-validated configurations.
Ships with multi-token prediction plus DSpark and DFlash draft-model options for different serving loads.
Offers a standard checkpoint and an NVIDIA-optimized quantized version for supported hardware.
Includes weights, data, recipes, and compatibility with NVIDIA's fine-tuning and evaluation tools.
Training and benchmarks emphasize coding, terminal work, instruction following, and agentic execution.
Can run through NVIDIA's endpoint, partner providers, or self-hosted inference frameworks.
Process
Step 1
Identify repetitive agent steps that need speed and do not require the strongest available reasoning model.
Step 2
Select BF16 or NVFP4 based on hardware support, memory, quality requirements, and serving software.
Step 3
Serve the model through a compatible runtime and connect it to an agent harness with explicit tool schemas.
Step 4
Measure task success, tool-call correctness, latency, throughput, and cost on representative production traces.
Step 5
Escalate uncertain or complex tasks to a stronger model and constrain tools, credentials, data, and action permissions.
Cost
The model weights are downloadable under OpenMDW 1.1, and NVIDIA offers a free prototype endpoint. Production cost depends on self-hosted GPU infrastructure or the selected partner endpoint.
No model fee listed
Download checkpoints from NVIDIA's official Hugging Face repository under the OpenMDW 1.1 license.
Free
Evaluate the model interactively or through NVIDIA's free API endpoint.
Varies
Run on owned NVIDIA hardware or a compatible hosted inference provider.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Consumer
Choose Nemotron 3 Super when stronger reasoning is more important than Lightning's execution efficiency.
Explore Nemotron 3 Super →Consumer
Consider Qwen3.5 Small for another compact open-model family with different deployment tradeoffs.
Explore Qwen3.5 Small →Coding
Consider Meta Llama for a broader open-model ecosystem and a wider choice of model sizes.
Explore Meta Llama Models →Questions
It is NVIDIA's open 30B mixture-of-experts text model with about 3B active parameters, optimized for fast execution steps in autonomous agents.
NVIDIA describes it as an open model and releases weights, data, and recipes under the OpenMDW 1.1 license. Teams should review that license for their intended use.
NVIDIA lists a free prototype endpoint and downloadable model weights. Production cost comes from GPU infrastructure or a hosted inference provider rather than a universal per-token price.
Yes, on supported systems. NVIDIA lists single-GPU deployment on DGX Spark or H100 and also documents local workflows for hardware such as GeForce RTX 5090, with configuration-dependent limits.
The official model card lists up to a 1 million-token context on validated configurations.
The model card lists English and coding languages, plus Spanish, French, German, Italian, and Japanese.
Usually not for every step. A practical design routes routine execution to Lightning and escalates complex planning, ambiguous decisions, or high-risk actions to a stronger model or a human.
Bottom line
Nemotron 3.5 Lightning is compelling for teams that can operate open-model infrastructure and want a fast worker model inside an agent stack. Its value should be proven with task-level evaluations and routing, not assumed from token speed or vendor benchmarks alone.
Visit Nemotron 3.5 Lightning website ↗
Muse Glimmer - Meta's open-weights local model for on-device agents

Grok 4.6 - SpaceXAI's new near-frontier model with strong agentic capabilities
Hint - Martha Stewart's AI home app for maintenance, repairs, and fair quotes
Gemini Flash 3.7 - Google’s upgraded fast, cheap and capable mid-class model

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.