Visual coding and interface work
Developers can give the model screenshots, page images, websites, or screen recordings as context for frontend, game, and GUI tasks.
Independent tool overview
GLM-5.3-Flash is Z.AI's efficiency-focused multimodal model for coding, agentic tool use, visual tasks, and professional document workflows, with a 1M-token context window and low per-token API pricing.
Visit the official GLM-5.3-Flash site ↗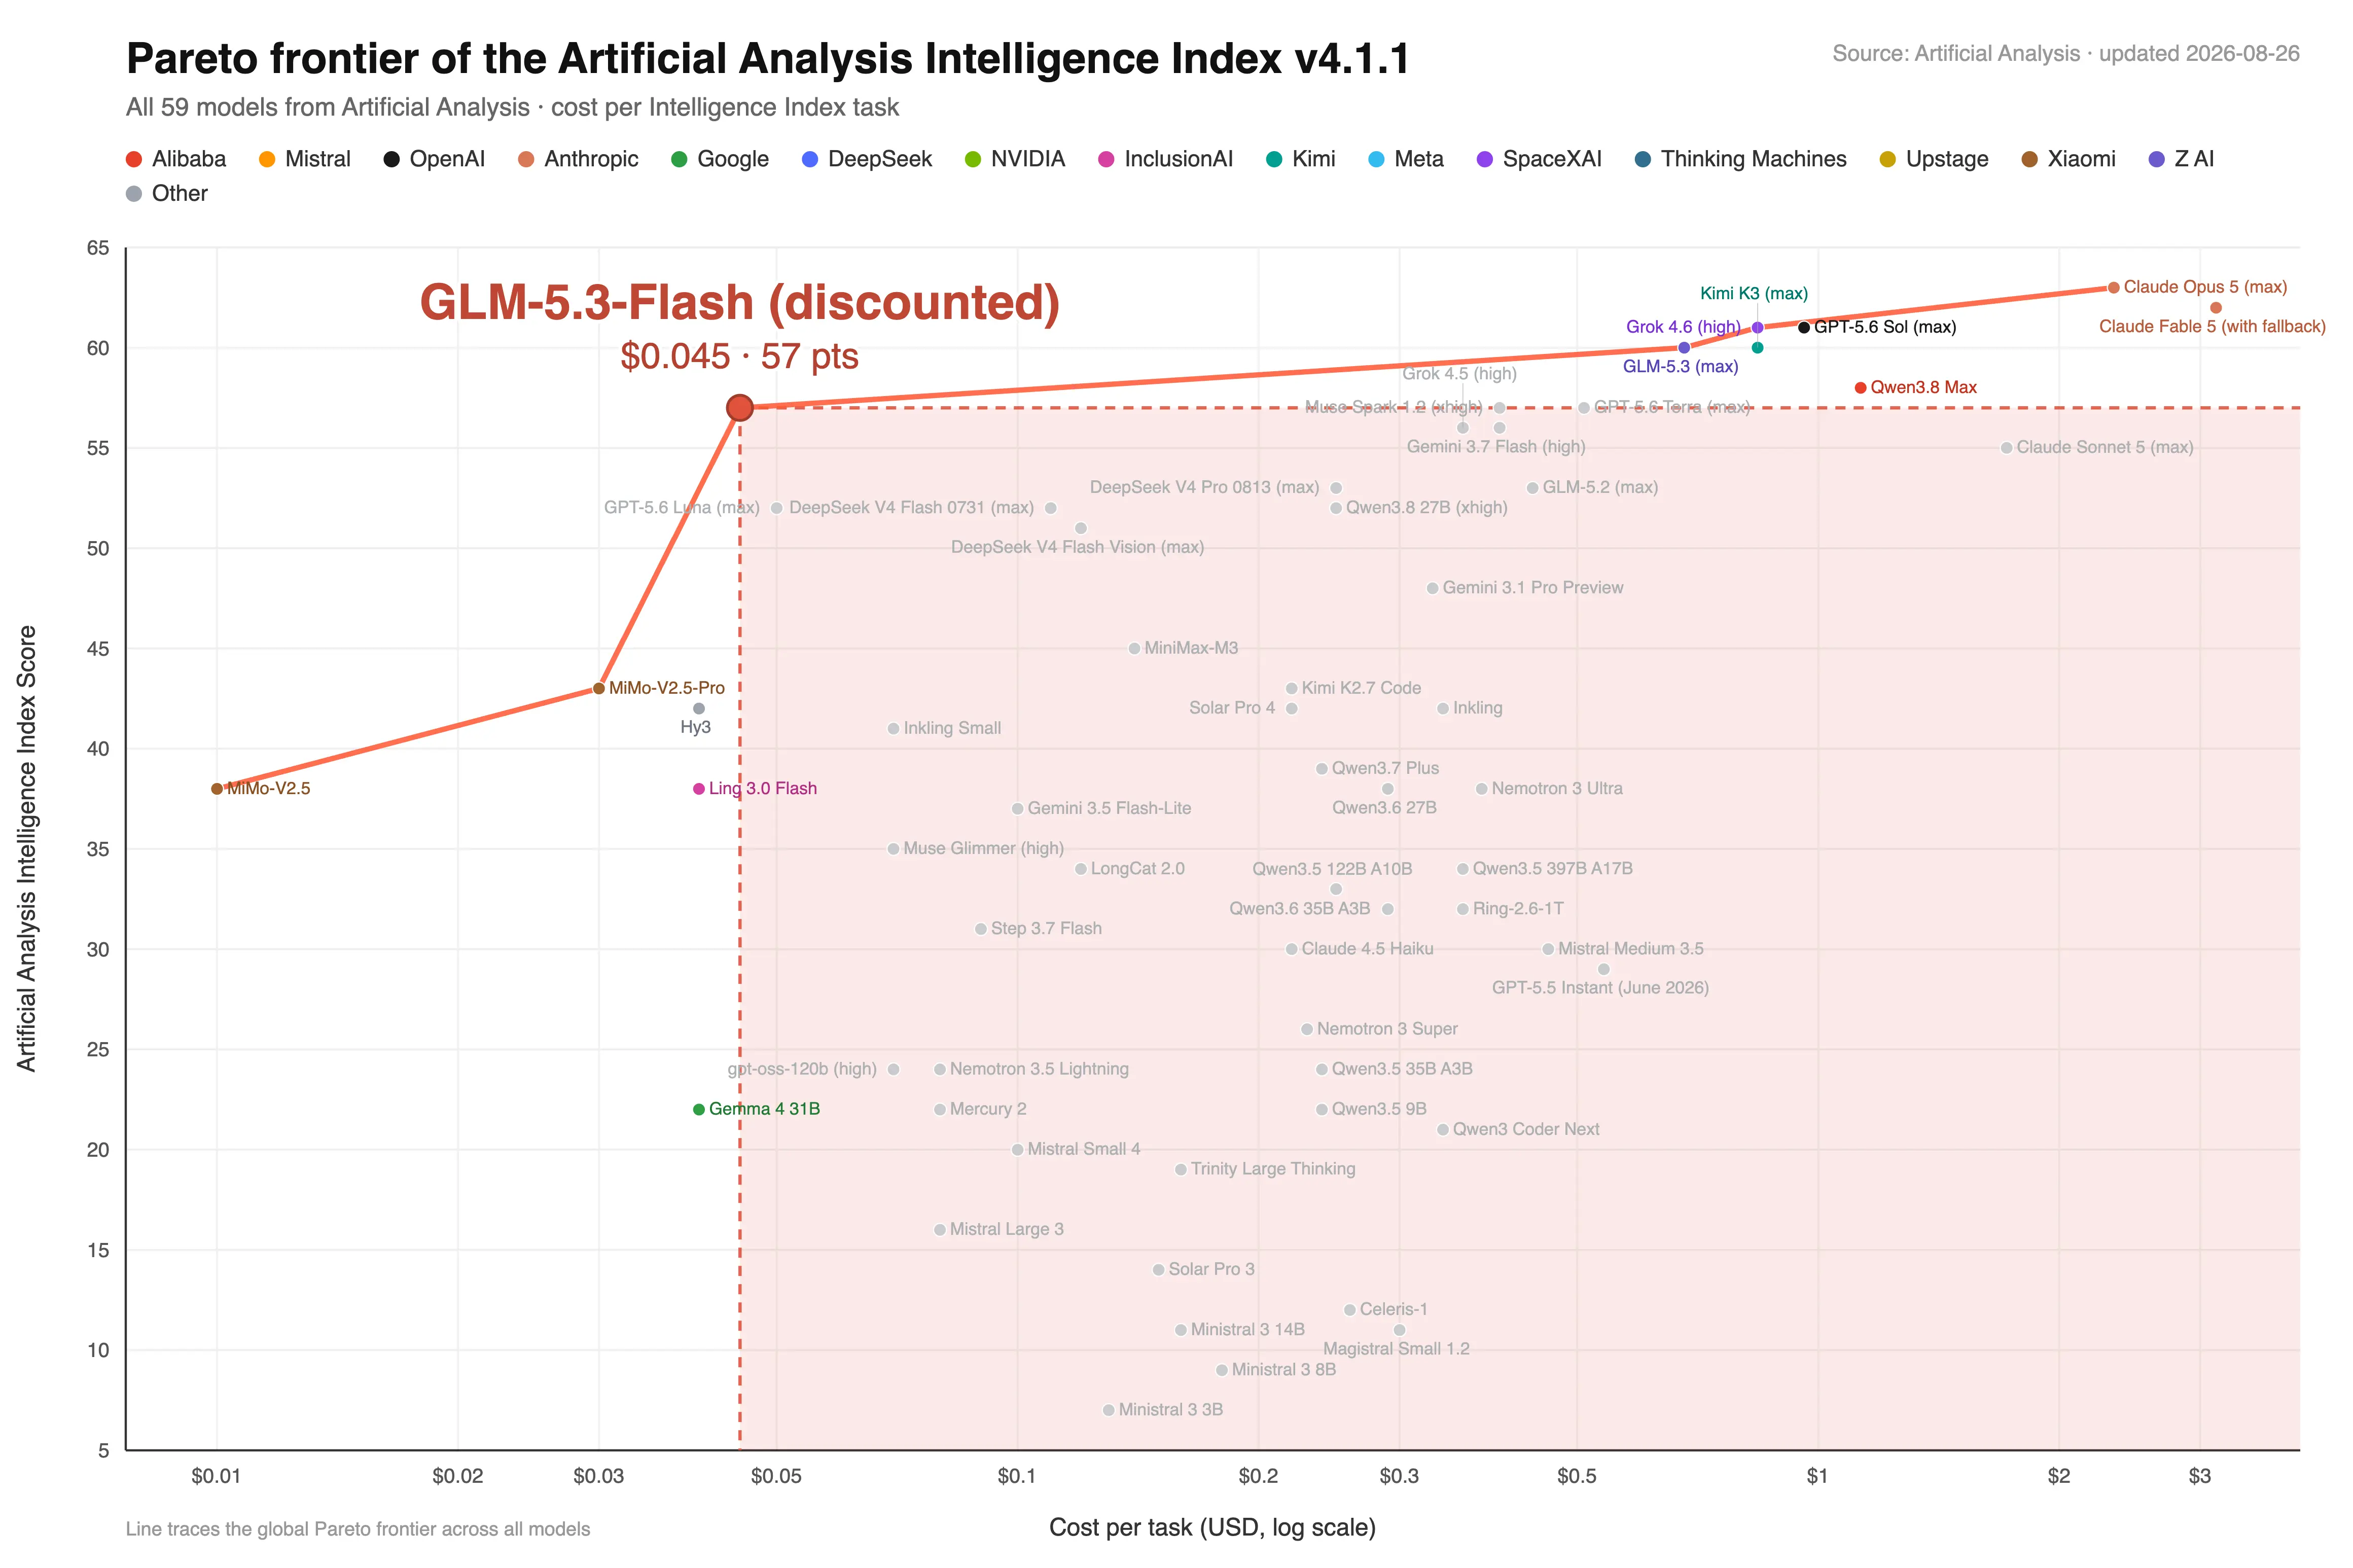
Overview
GLM-5.3-Flash is Z.AI's first native multimodal model in the GLM-5 family. It accepts text, images, video, and files, then produces text output for coding, research, document, interface, and computer-use workflows.
The model is designed around cost-efficient long-context work. Z.AI lists 320 billion total parameters with 18 billion activated, a hybrid sparse-and-linear-attention architecture, a 1M-token context window, and up to 128K output tokens. It is available through the Z.AI API and GLM Coding Plan.
Its strongest differentiator is the combination of visual understanding and agentic coding. Z.AI documents workflows that inspect screenshots or rendered interfaces, operate tools, generate editable office files, and iteratively check the resulting output. These capabilities still depend on the surrounding agent, tools, permissions, and validation loop rather than the model alone.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Developers can give the model screenshots, page images, websites, or screen recordings as context for frontend, game, and GUI tasks.
The 1M-token context window and tool-calling support suit agents that must work across large codebases, documents, and extended task histories.
The Flash model targets teams that need multimodal reasoning and coding capabilities at substantially lower token prices than Z.AI's flagship GLM-5.3 model.
Z.AI positions the model for research, analysis, and generation of presentations, PDFs, documents, and spreadsheets when paired with the right tools.
Capabilities
GLM-5.3-Flash can process text, images, video, and files within the same workflow, including multiple images in an API request.
The model supports up to 1M tokens of context and up to 128K generated tokens for unusually large inputs and long deliverables.
It can use screenshots, rendered results, and interaction feedback to help build and refine interfaces, games, 3D scenes, and other visual software.
The API supports function calling, streaming, tool-streaming output, context caching, and structured output for integration into agent systems.
Z.AI combines sparse and linear attention with 18B activated parameters out of 320B total to reduce long-context computation and cache requirements.
When connected to file-generation and inspection tools, the model can support workflows involving PPTX, PDF, DOCX, and XLSX deliverables.
Process
Step 1
Use model code glm-5.3-flash through the Z.AI API or select it in a compatible tool through the GLM Coding Plan.
Step 2
Supply text, files, images, video, or interface references, along with the intended output and any constraints.
Step 3
Enable function calls, file utilities, browsers, or computer-use tools that the task actually needs, with appropriately limited permissions.
Step 4
Review tool calls and generated artifacts, render visual outputs where relevant, and independently test code, calculations, citations, and file quality.
Cost
Z.AI charges for GLM-5.3-Flash by token through its API. A 50% launch promotion is active through September 9, 2026 at 24:00 UTC+8; the official pricing page also lists the higher standard rates that follow. GLM Coding Plan subscriptions use a separate points-based quota system.
$0.075 input / $0.25 output per 1M tokens
Temporary 50% pricing through September 9, 2026 at 24:00 UTC+8.
$0.15 input / $0.50 output per 1M tokens
The list prices shown by Z.AI alongside the temporary launch discount.
Subscription pricing varies
Personal and Team subscriptions provide points-based usage in supported coding tools, with GLM-5.3-Flash receiving three times the quota of GLM-5.3.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Consumer
Choose GLM-5.3 when you want Z.AI's higher-priced flagship model instead of the efficiency-focused Flash variant.
Explore GLM-5.3 →Consumer
Consider Gemini 3.5 Flash for another current speed-and-cost-focused multimodal model from a major API provider.
Explore Gemini 3.5 Flash →Project Management
Consider Claude for a polished general-purpose assistant and API ecosystem with strong coding, document, and tool-use workflows.
Explore Claude →Questions
GLM-5.3-Flash is Z.AI's efficiency-focused native multimodal model for coding, agentic tool use, visual work, research, and document workflows.
The official product name is GLM-5.3-Flash. Some older links or slugs may reverse the numbers, but Z.AI's documentation and API model code use glm-5.3-flash.
The official documentation lists text, images, video, and files as supported inputs. Output is text.
GLM-5.3-Flash supports a 1M-token context window and up to 128K output tokens.
Through September 9, 2026 at 24:00 UTC+8, Z.AI lists promotional prices of $0.075 per 1M input tokens, $0.015 per 1M cached input tokens, and $0.25 per 1M output tokens. Standard prices are twice those amounts.
It can plan and generate the content or instructions, but producing and visually validating finished PPTX, PDF, DOCX, or XLSX files requires an agent environment with the relevant file and rendering tools.
Bottom line
GLM-5.3-Flash is a compelling option for teams that want multimodal coding and agent capabilities with an unusually large context window at a low API price. The value case is strongest when buyers test it on real long-context, visual, and tool-use workflows rather than relying on vendor benchmarks. Budget with the standard rates unless work will finish during the launch promotion, and plan for independent validation of any code, research, or generated files.
Visit GLM-5.3-Flash website ↗
Perplexity's agent that runs fully on personal Nvidia hardware
Google's strongest Flash model yet for coding and agents
ChatGPT for Teens - OAI's new teen experience pairing guided learning with default safety limits
Anthropic's new flagship, top-rated model

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.