Realtime conversational apps
Stream speech into voice agents, companions, tutors, support experiences, or interactive characters where delay breaks the conversation.
Independent tool overview
Inworld Realtime TTS is a developer-focused voice platform for low-latency speech synthesis, multilingual voice cloning, and conversational applications. Its current TTS-2 family combines streaming, natural-language direction, and spend-based pricing.
Visit the official Inworld Realtime TTS site ↗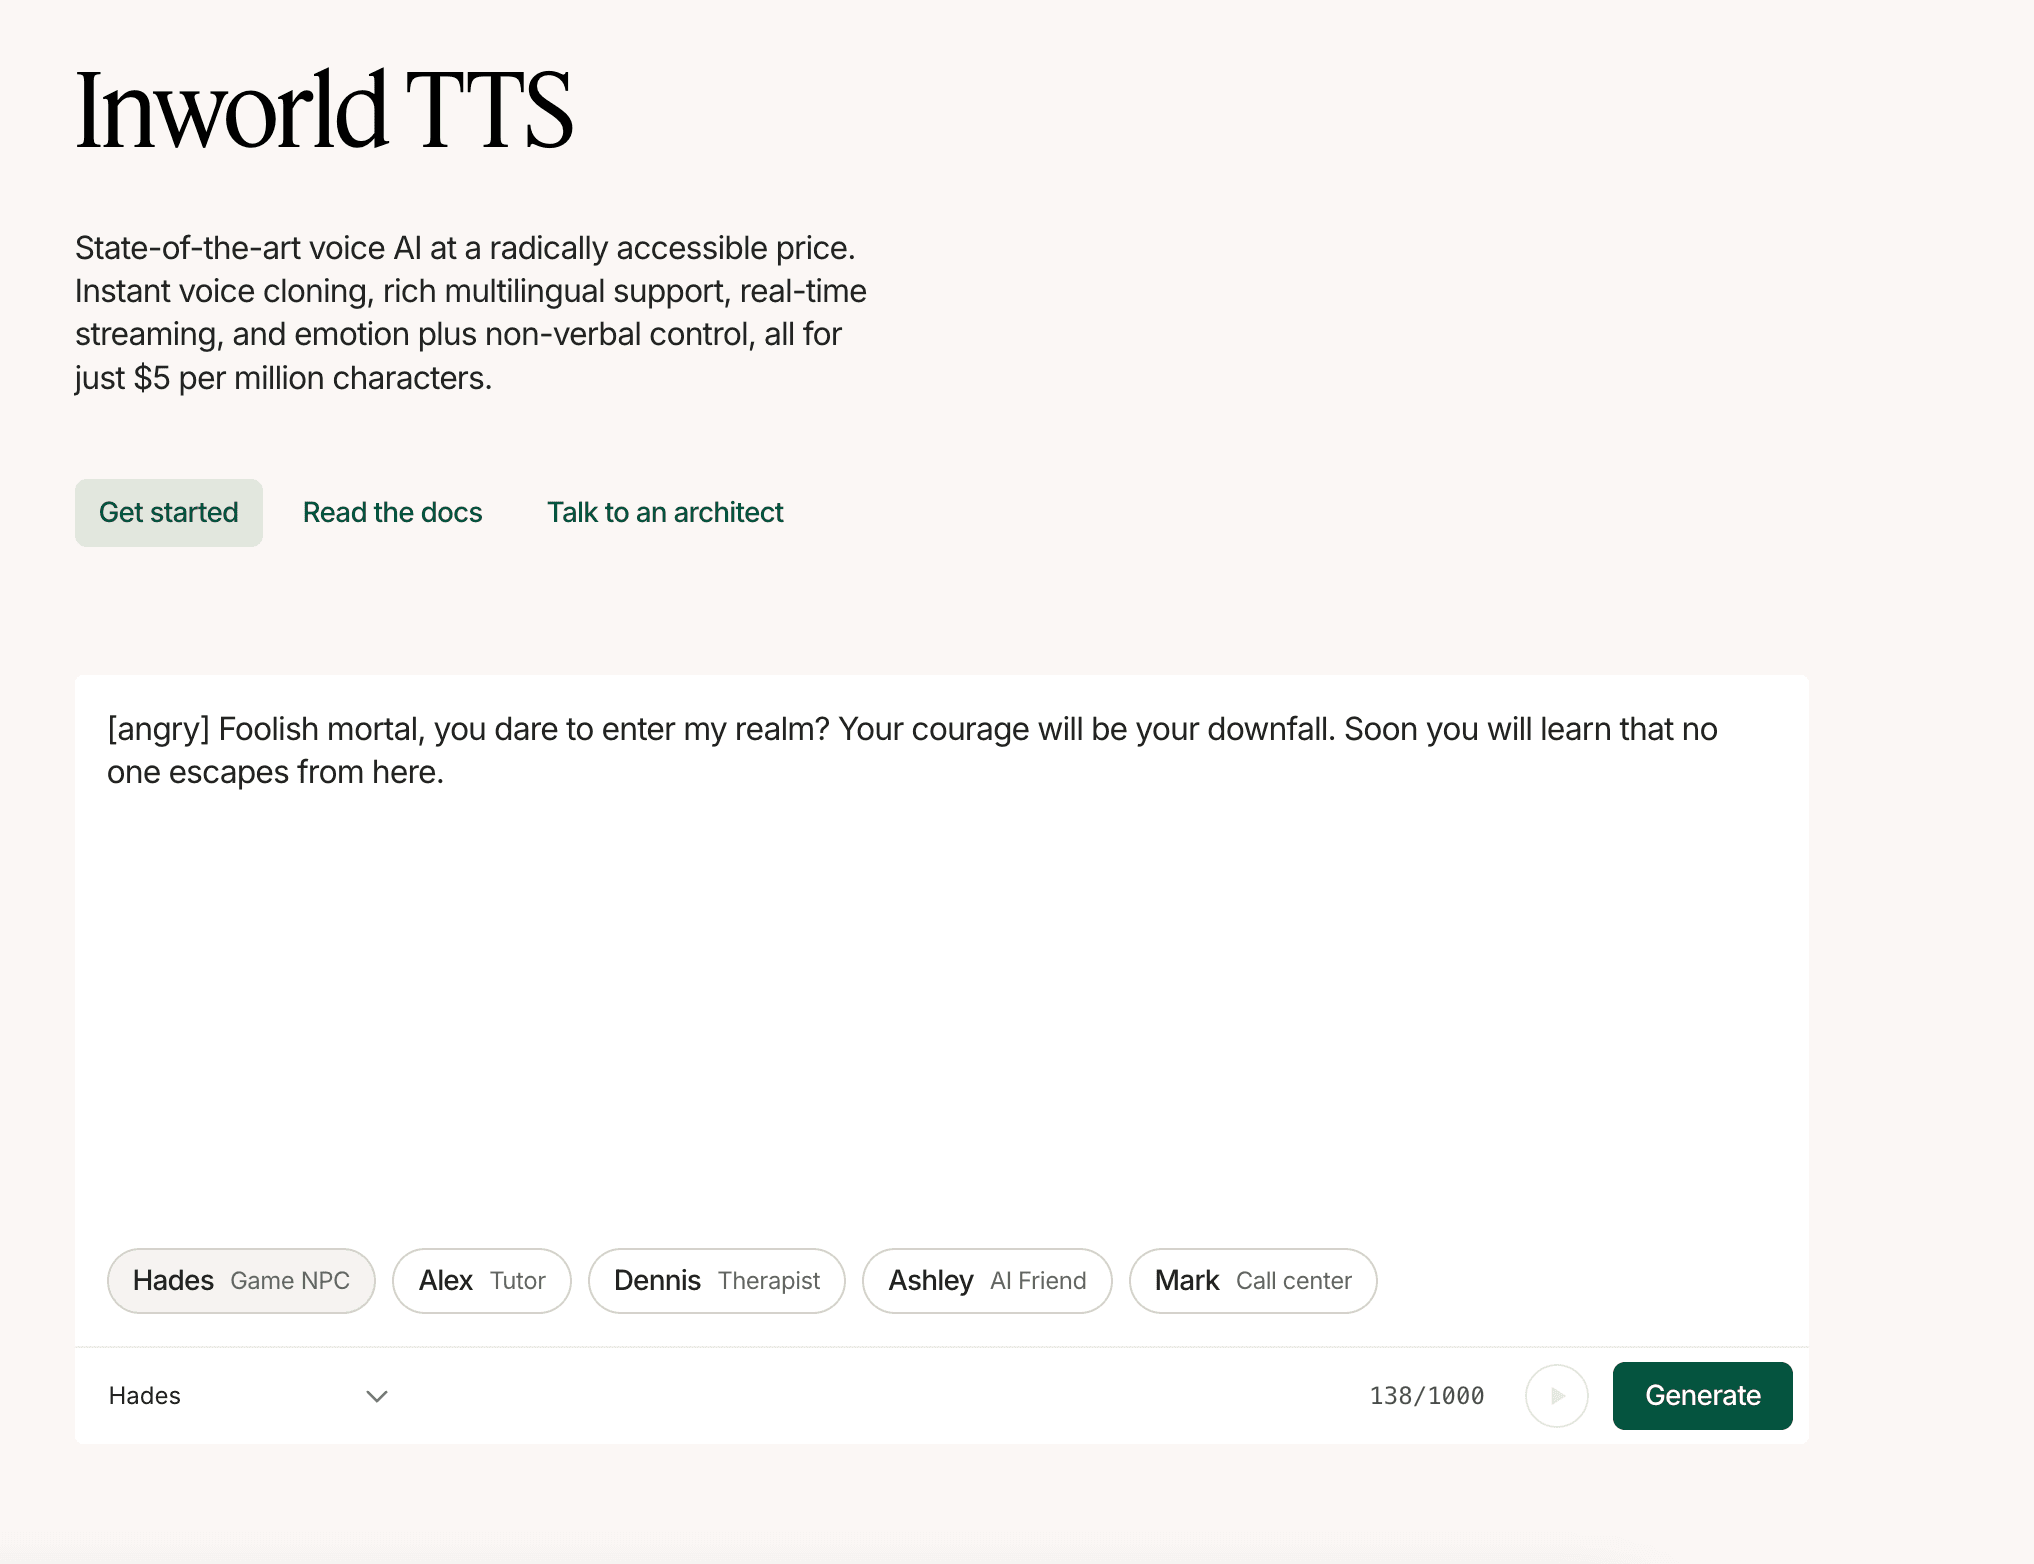
Overview
Inworld Realtime TTS converts text into speech for voice agents, games, accessibility tools, dubbing, and content production. It is designed around streaming APIs and low time-to-first-audio rather than only exporting finished narration files.
The flagship Realtime TTS-2 model supports expressive direction, conversational context, non-verbal cues, custom pronunciation, timestamps, and cross-lingual voice identity across more than 200 languages. TTS-2 Flash trades some control for an even lower latency and price floor.
Developers can start through a Playground or API, clone a voice from a short sample, or design one from a text description. Production buyers should compare real latency, error rates, language quality, concurrency, data handling, and consent workflows using their own traffic.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Stream speech into voice agents, companions, tutors, support experiences, or interactive characters where delay breaks the conversation.
Keep one voice identity across many languages for localization, translation, and international user experiences.
Use spend tiers to lower per-character rates as a production workload grows.
Create instant clones from short samples, commission higher-fidelity professional clones, or design a synthetic voice from prose.
Capabilities
Inworld's flagship model supports expressive speech, conversational context, natural-language steering, and multilingual voice consistency.
A lower-latency, lower-cost model for applications where response speed and scale matter more than the full steering feature set.
Stream audio chunks for live experiences or use non-streaming generation for narration, notifications, and content pipelines.
Build an instant clone from roughly 5 to 15 seconds of audio, use a professional clone for higher fidelity, or describe a new voice in text.
Direct delivery with bracketed natural-language instructions and supported non-verbal cues such as laughs, breaths, sighs, coughs, and yawns.
Use custom pronunciation, speaking-rate and temperature controls, timestamps, multiple audio formats, workspaces, and higher concurrency tiers.
Higher tiers can add zero data retention, HIPAA and BAA support, data residency, an SLA, a DPA, or on-prem deployment.
Process
Step 1
Use the Playground with real scripts, names, numbers, interruptions, and target languages rather than judging a polished demo.
Step 2
Start with TTS-2 for maximum expressiveness and compare Flash when the application's latency or cost target is tighter.
Step 3
Connect the streaming or batch endpoint, then monitor time to first audio, total generation time, pronunciation failures, reconnects, and spend.
Step 4
Document consent and permitted uses before cloning, protect API keys, set budgets, review generated speech, and disclose synthetic audio where appropriate.
Cost
Inworld uses monthly credits across its platform. Higher commitments lower the per-character TTS rate, and overages are charged at the plan's rate. Annual billing is advertised with two months free.
Start free
For evaluation and prototypes without a monthly commitment.
$25/month
For content creation and small projects.
$100/month
For growing projects and small teams.
$300/month
For production applications.
$1,500/month
For larger deployments with compliance needs.
Custom
For the lowest unit rates, custom terms, and deployment control.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Sales
Consider Vapi when you want a broader voice-agent orchestration layer that can combine multiple model and telephony providers.
Explore Vapi →Content Creator
Consider ElevenLabs' ChatGPT tool for a simpler, creator-oriented path to generating speech without building directly against an API.
Explore ElevenLabs Text To Speech GPT →Business Operations
Consider Speechify when the primary need is listening to documents and articles rather than embedding realtime speech in an application.
Explore Speechify →Questions
It is an API and Playground for generating streaming or batch speech, with custom voices, cloning, voice design, multilingual output, and controls for conversational applications.
On-demand TTS-2 is $25 per million characters and TTS-2 Flash is $15. Monthly plans reduce those rates, with TTS-2 advertised as low as $5 per million characters at enterprise scale.
The On-Demand option starts free and advertises up to 70 minutes of included TTS. Additional use is billed at the on-demand character rate.
TTS-2 is the flagship model for maximum expressiveness, contextual delivery, and natural-language steering. Flash targets the lowest latency and cost but omits some advanced steering and professional-cloning capabilities.
Yes. Instant cloning uses roughly 5 to 15 seconds of audio, while professional cloning uses a larger clean dataset for higher fidelity. You must confirm you have the rights to clone the voice.
Inworld includes a commercial license in its published plans, subject to its terms and your rights to any source material or cloned voice.
Bottom line
Inworld Realtime TTS is a strong shortlist candidate for developers building latency-sensitive, multilingual voice products. TTS-2 offers unusually direct expression controls, while Flash and the spend tiers create a credible scale path. Run a production-shaped bake-off before committing, and treat voice consent, language QA, data retention, and real concurrency as purchasing requirements.
Visit Inworld Realtime TTS website ↗
Canva Creative Operating System - A supercharged Visual Suite with a design-focused AI model, video tools, marketing upgrades, and more.
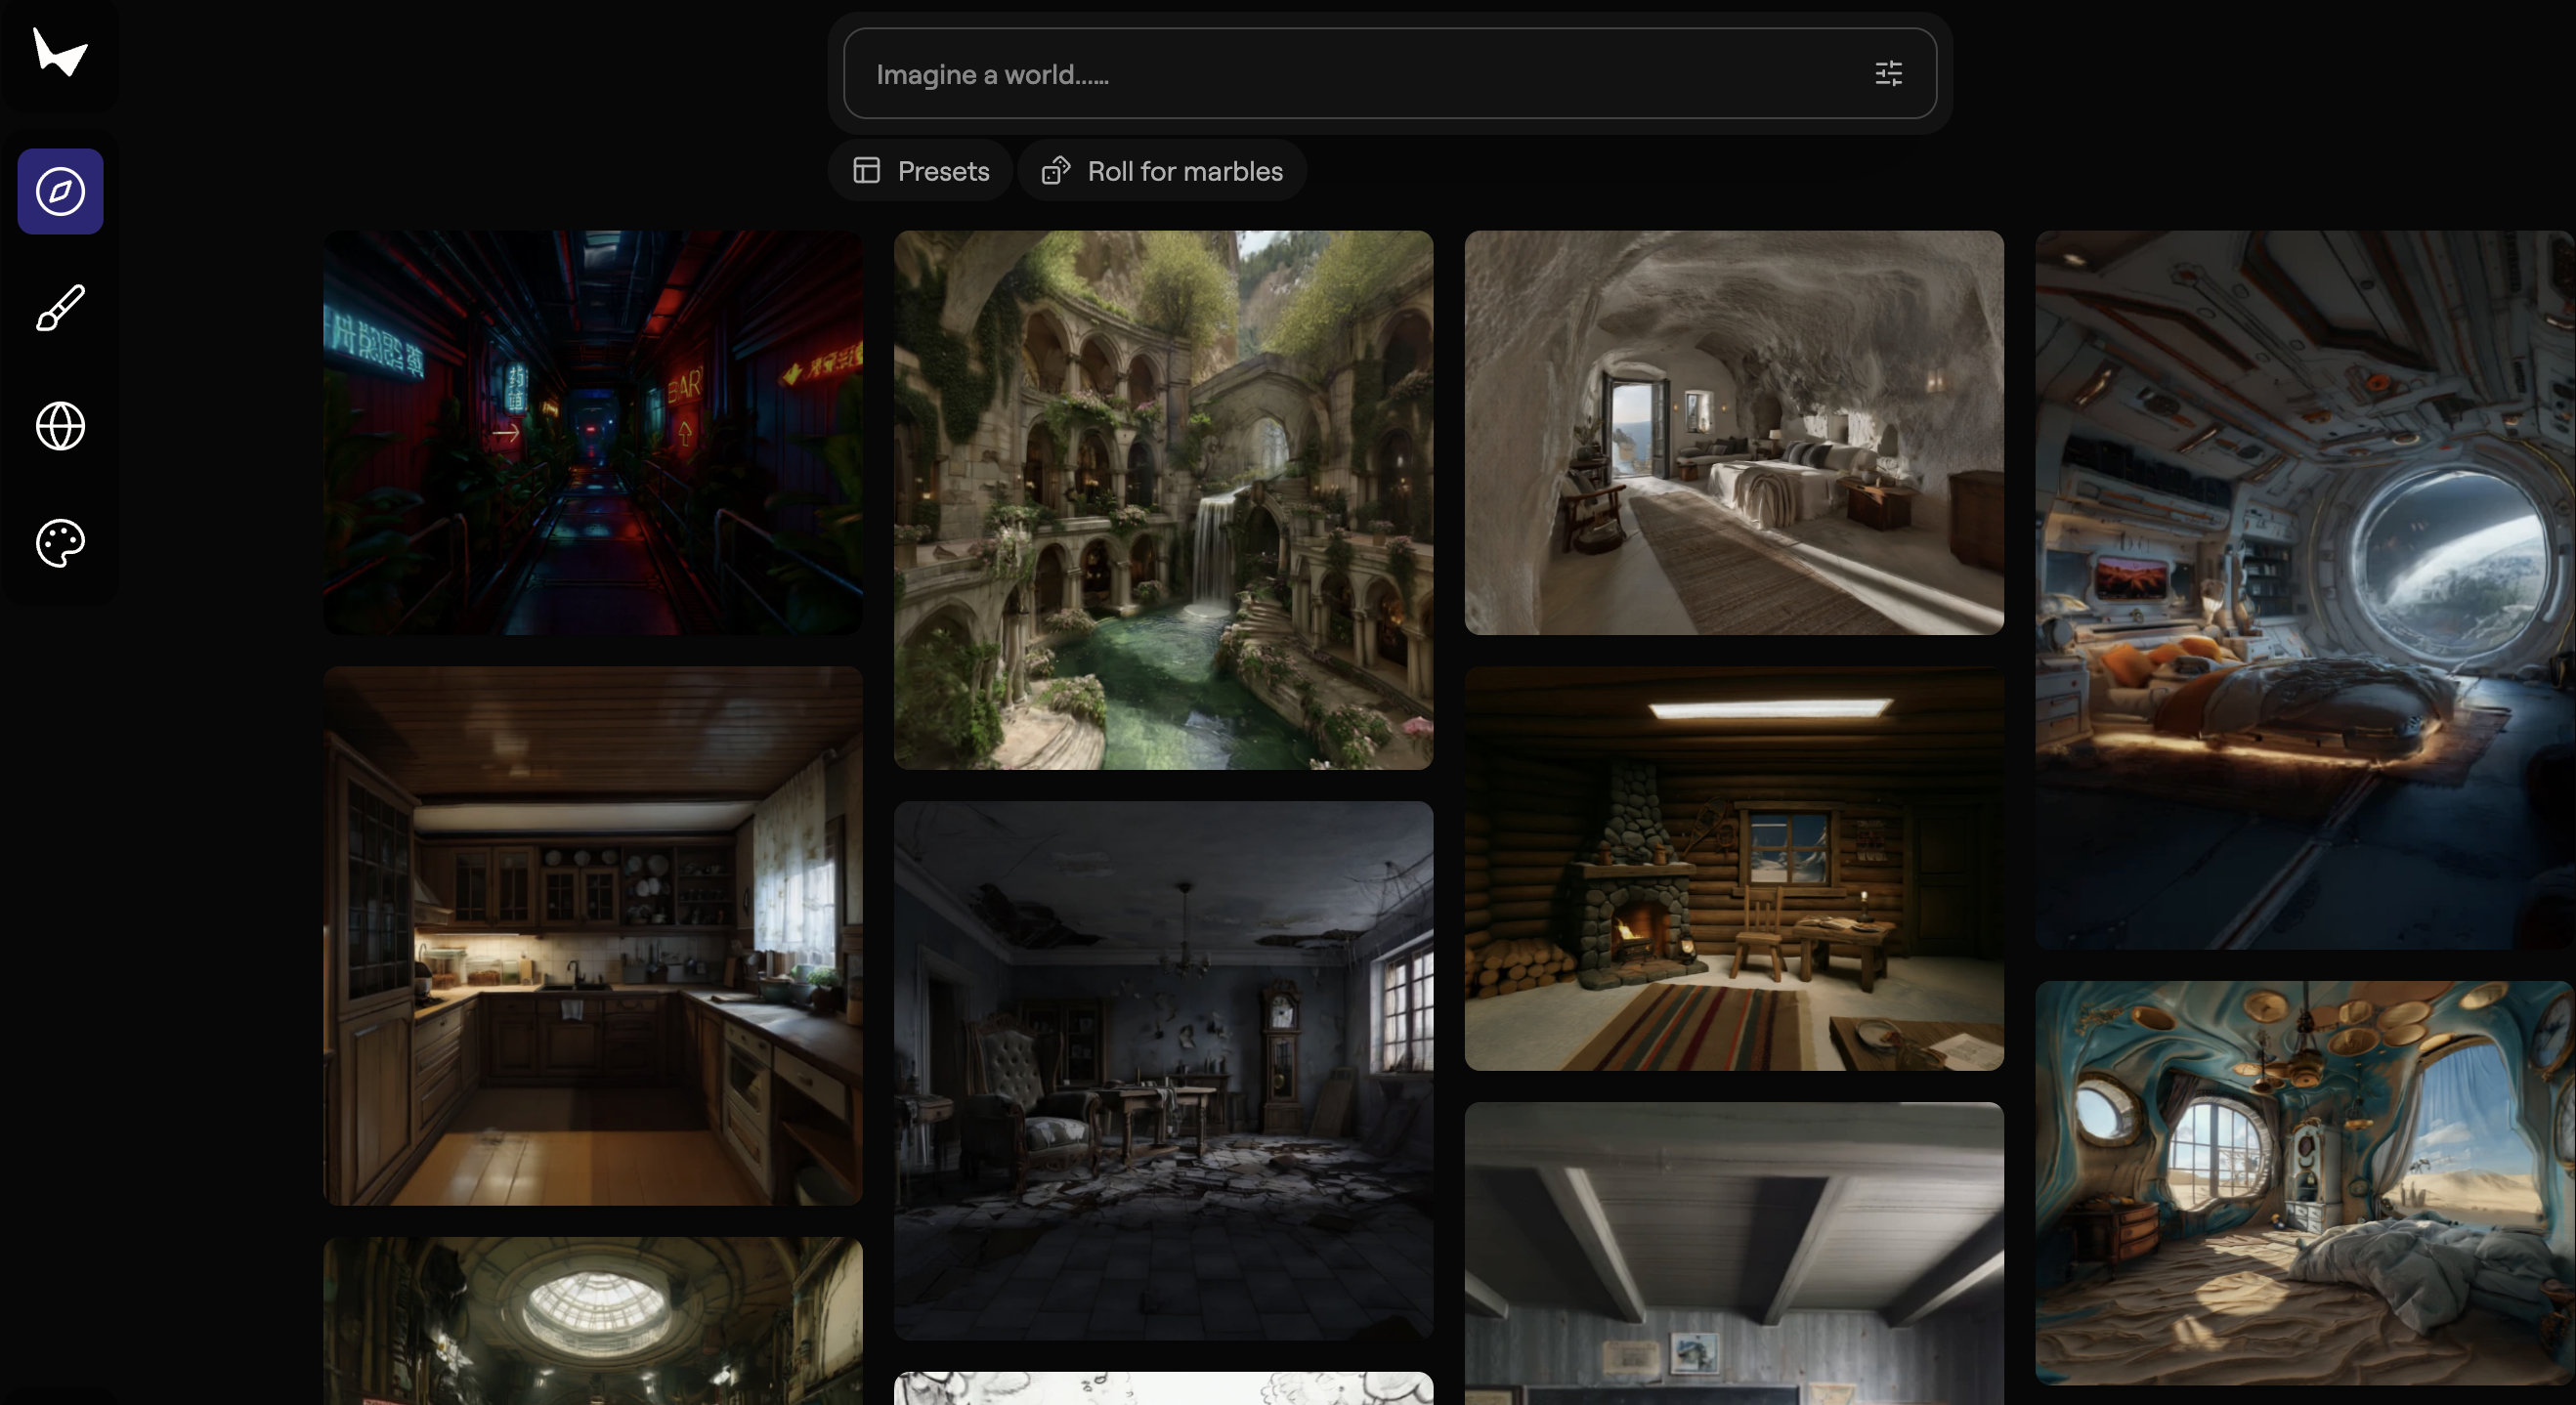
Marble - World Labs' model for creating persistent, high-fidelity 3D worlds from images, videos, and text prompts.

LTX-2-Fast
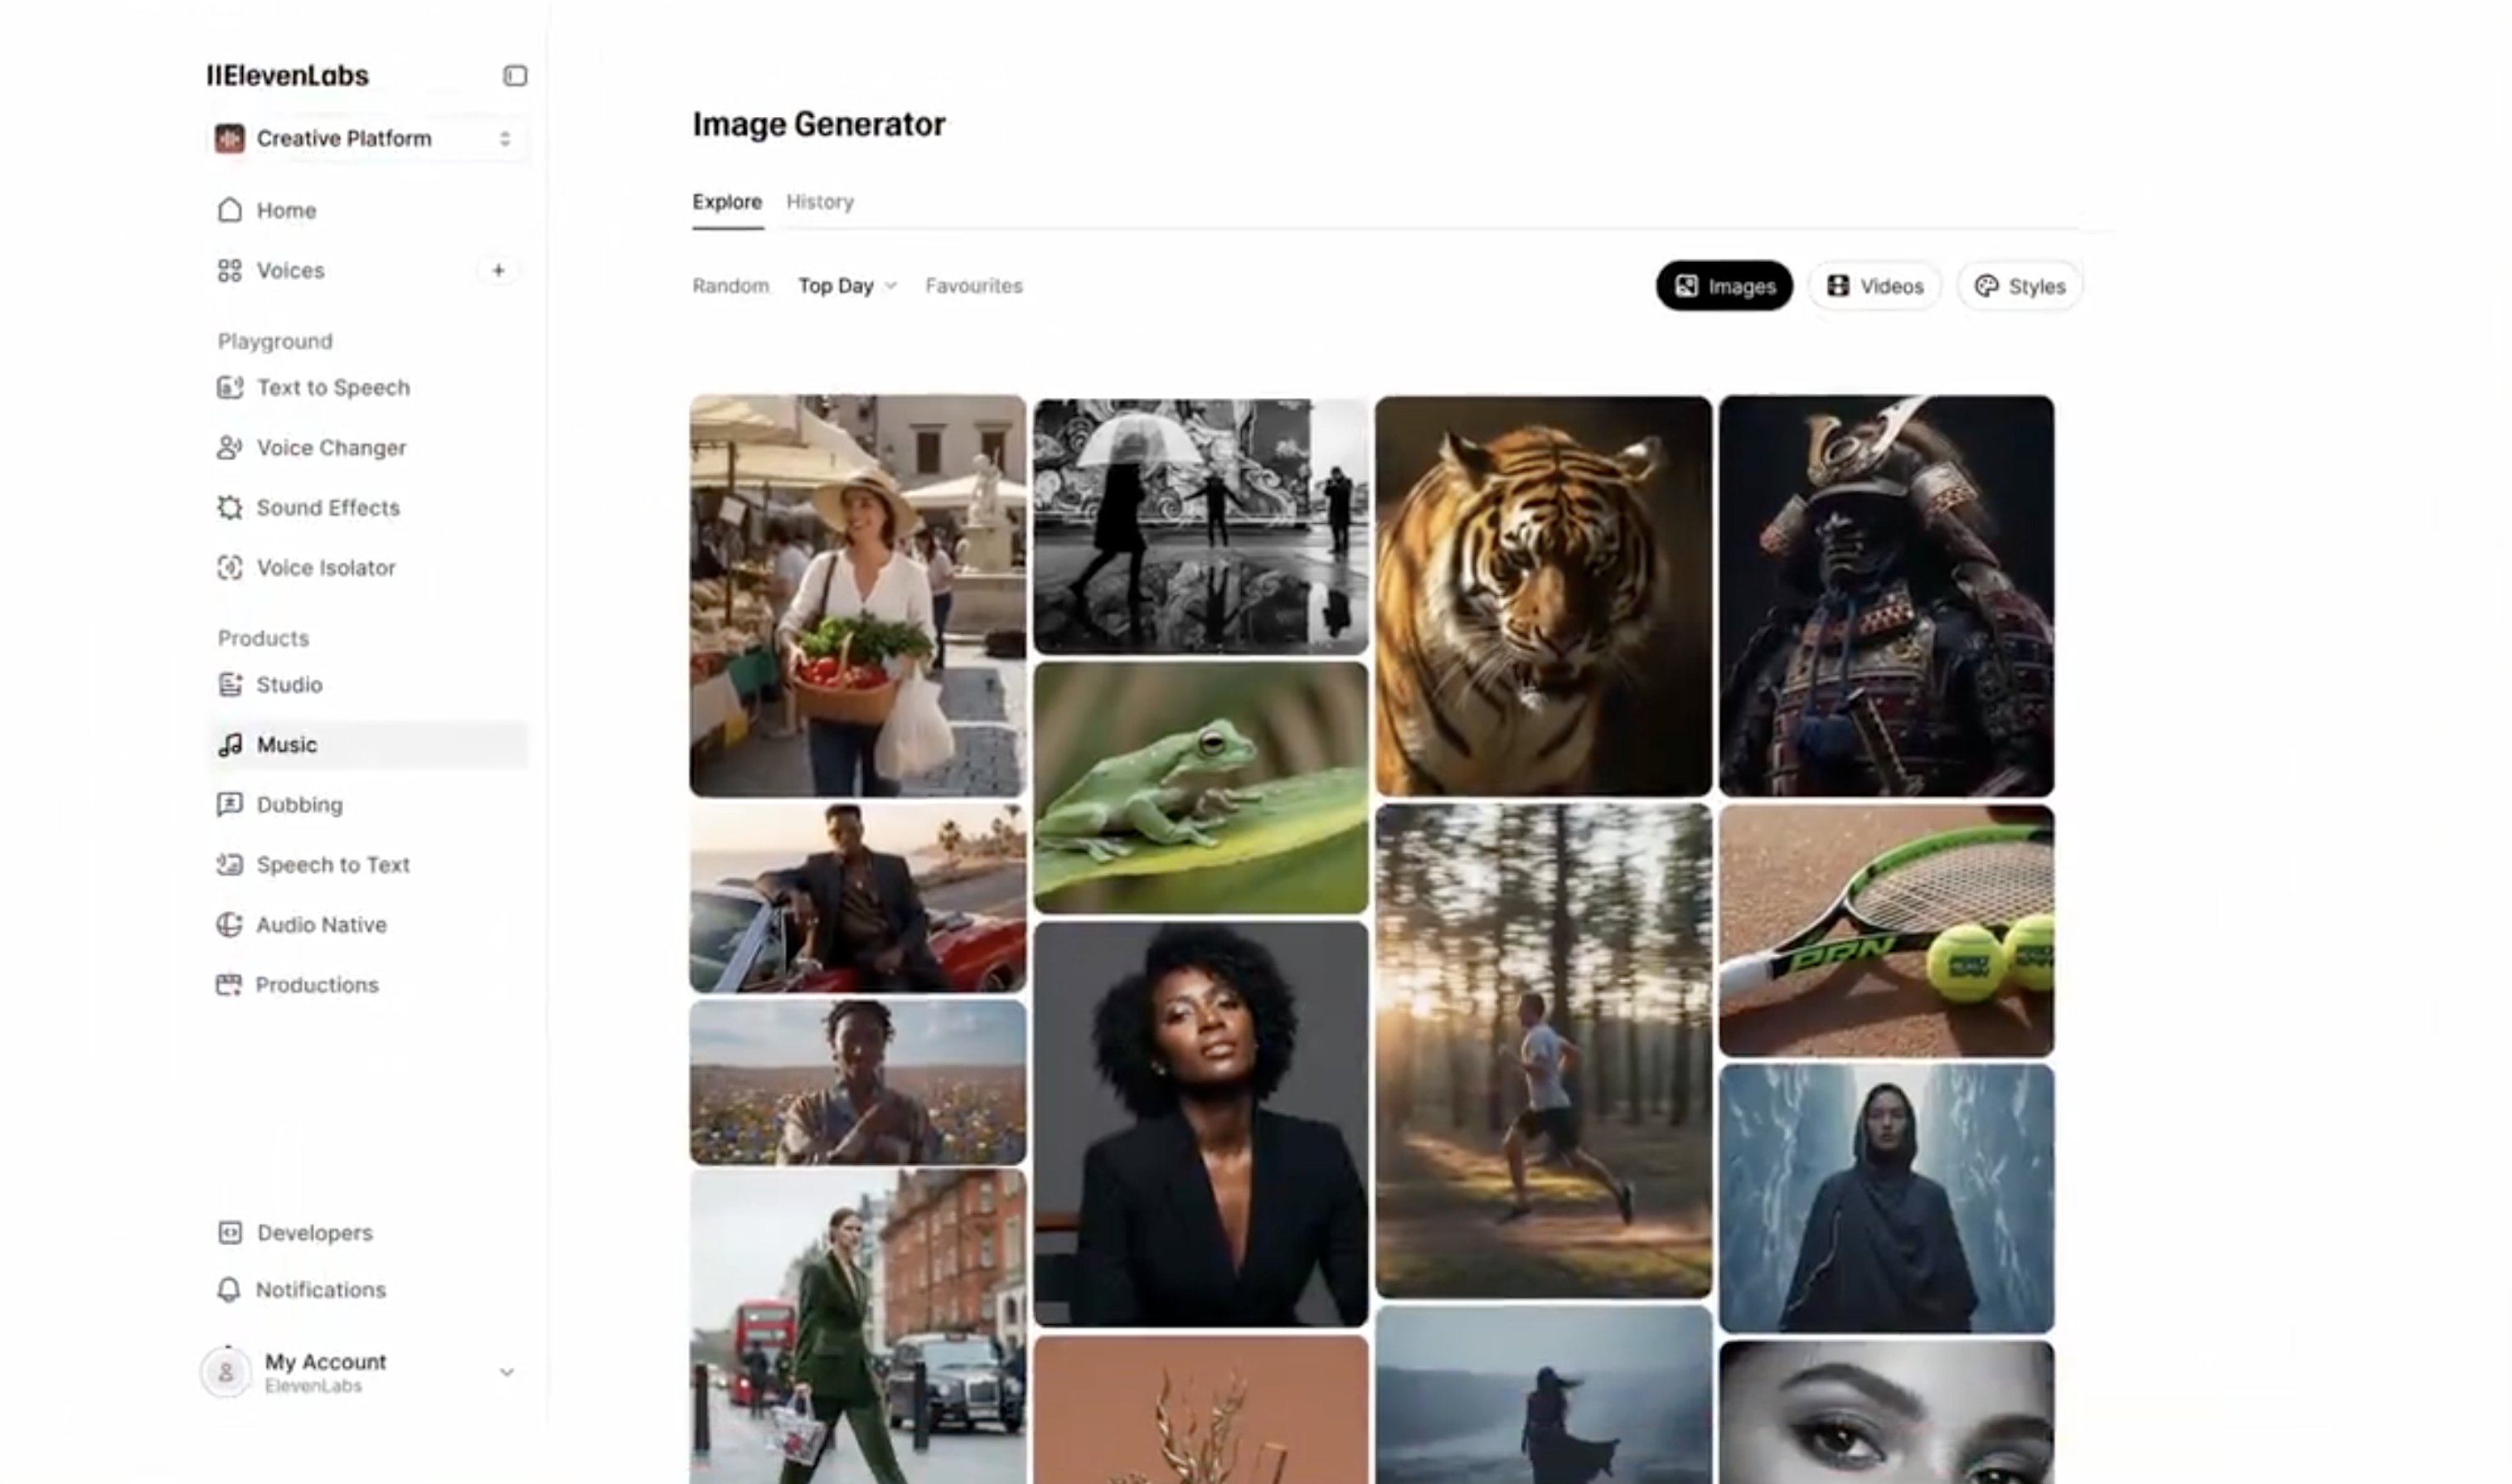
ElevenLabs Image & Video - Generate with top models, then layer in high quality voices, music, and sound effects all in one platform

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.
Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.
To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.
Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.
Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.