Self-hosted narration
Teams generating multilingual product narration, explainers or accessibility audio with an open model and a fixed voice roster.
Independent tool overview
Qwen3-TTS CustomVoice 1.7B is an Apache-licensed text-to-speech model that speaks ten languages through nine built-in voices, with streaming output and natural-language control over delivery.
Visit the official Qwen3-TTS CustomVoice 1.7B site ↗
Overview
Qwen3-TTS CustomVoice 1.7B is the preset-speaker member of Qwen's open speech-generation family. It turns text into speech using nine named voices and can follow instructions about emotion, pace, tone and prosody.
The model supports Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish and Italian. Qwen recommends using each speaker's native language for the best quality, although every listed speaker can generate any supported language.
Despite the original directory description, this CustomVoice checkpoint does not clone a person's voice from a three-second recording. Rapid voice cloning belongs to the separate Qwen3-TTS Base checkpoints; VoiceDesign is another separate model. That distinction matters for both product selection and consent controls.
Use cases
The strongest fit depends on the job you need the product to complete, not the size of its feature list.
Teams generating multilingual product narration, explainers or accessibility audio with an open model and a fixed voice roster.
Dialogue and character lines that benefit from instructions for emotion, rhythm, speaking rate and delivery.
Developers testing streaming speech for assistants or interactive experiences before selecting production infrastructure.
Capabilities
The official roster includes Vivian, Serena, Uncle_Fu, Dylan, Eric, Ryan, Aiden, Ono_Anna and Sohee.
Generates Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish and Italian.
A free-text instruction can guide emotion, tone, rate and prosody for the 1.7B checkpoint.
The family supports streaming and non-streaming generation; Qwen reports end-to-end first-packet latency as low as 97 ms under its test conditions.
The Python interface accepts lists of text, language, speaker and instruction values for multiple outputs.
The qwen-tts package loads checkpoints directly and includes a local web demo command.
Weights are available through Hugging Face and ModelScope under Apache 2.0, with vLLM-Omni offline-inference examples.
Process
Step 1
Use CustomVoice for the nine preset speakers, VoiceDesign for a described synthetic persona, or Base for consented reference-audio cloning.
Step 2
Use the current qwen-tts package and a compatible GPU stack; Qwen recommends FlashAttention 2 to reduce memory use where supported.
Step 3
Set the known target language explicitly, choose a speaker and write a concise performance instruction without putting secrets in the text.
Step 4
Test pronunciation, names, numbers, code-switching, emotion, noise, latency and consistency across the actual scripts and target devices.
Step 5
Have a fluent reviewer listen to the full output, correct errors, document the synthetic voice and obtain the rights needed for script, music and distribution.
Cost
The CustomVoice checkpoint is free under Apache 2.0, but self-hosting requires suitable compute. Alibaba Cloud also sells related managed Qwen3-TTS speech APIs; those model IDs are hosted services and should not be assumed to be the identical 1.7B checkpoint.
Free under Apache 2.0
Download and operate the 1.7B CustomVoice weights.
Compute-dependent
Run locally or on rented accelerators using qwen-tts or a compatible runtime.
$0.115 per 10,000 characters
International Singapore list price for the related qwen3-tts-instruct-flash hosted model.
Pricing checked . Check current pricing at the source ↗
Assessment
Compare
The right alternative depends on the specific output, workflow, controls and budget your project requires.
Marketing
A managed commercial speech platform with voice libraries, cloning and production tooling for teams that do not want to self-host.
Explore ElevenLabs →Content Creator
An open Microsoft speech model oriented toward long-form and multi-speaker generation.
Explore VibeVoice →Questions
It is an open Qwen text-to-speech checkpoint with nine preset speakers, ten languages, streaming generation and instruction control over delivery.
No. The three-second rapid-cloning capability belongs to Qwen3-TTS Base checkpoints. CustomVoice uses a fixed list of preset speakers.
Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish and Italian. Qwen recommends each preset speaker's native language for the strongest quality.
Vivian, Serena, Uncle_Fu, Dylan, Eric, Ryan, Aiden, Ono_Anna and Sohee. They cover Chinese and regional Chinese profiles plus native English, Japanese and Korean voices.
The model weights and repository are published under Apache 2.0. You still pay for infrastructure and must comply with content, voice, privacy and distribution rights.
Yes, on compatible hardware. Qwen documents its qwen-tts Python package and local demo, recommends FlashAttention 2 where supported, and provides vLLM-Omni offline examples.
The open checkpoint has no model license fee. Self-hosting costs depend on hardware and traffic. A related Alibaba Cloud Instruct API is listed at $0.115 per 10,000 characters in Singapore, but it is not identified as the identical 1.7B checkpoint.
Obtain rights to scripts and voices, disclose synthetic audio, block impersonation and fraud, protect logs and credentials, watermark or retain provenance where appropriate, and require human approval for sensitive messages.
Bottom line
Qwen3-TTS CustomVoice 1.7B is a practical open option when nine stable preset speakers and multilingual instruction control are enough. Its biggest documentation trap is the product boundary: it does not perform the family's three-second voice cloning, so teams needing a copied or newly designed identity must choose another checkpoint and apply stricter consent controls.
Visit Qwen3-TTS CustomVoice 1.7B website ↗

Tiny Aya - Cohere Labs' new open-source multilingual small model covering 70+ languages in just 3.35B parameters
Claude Sonnet 4.6 - Anthropic's upgraded mid-tier model rivaling Opus at 1/5 the cost with 1M-token context
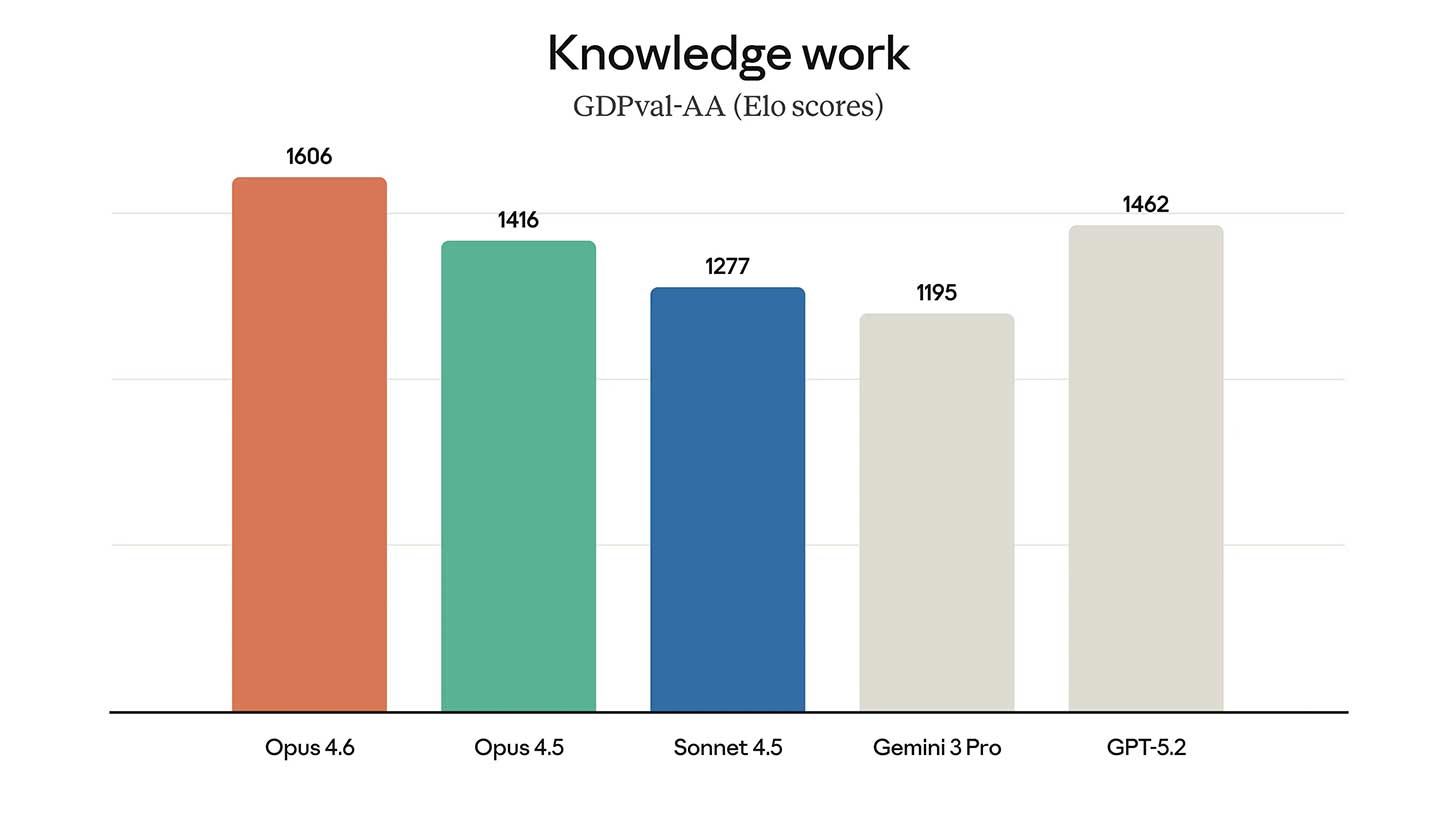
Claude Opus 4.6 - Anthropic's upgrade to its most powerful model line, featuring multi-agent collaboration, 1M context window, and new Office integrations
Lyria 3 - Google's new AI music generation model for creating 30-second, customizable audio clips from text, image, or video prompts.

Get access to all our AI courses, hundreds of real-world AI use cases, live expert-led workshops, an exclusive network of AI early adopters, and more.

Get unlimited access to all of our current & upcoming industry-specific AI courses for the duration of your subscription.

To keep up with the rapid pace of AI, our team publishes AI implementation guides daily. Our library contains 300+ practical use cases to automate real-world work.

Join weekly, live, interactive sessions with industry leaders who are at the forefront of AI for hands-on implementation guidance and exclusive insights.

Network with an exclusive community of AI-first professionals who are working smarter with AI. Learn how early adopters are using AI in their work and businesses.